
Findings and field notes.
What our benchmarks found, how we run them, and notes on building AI products you can trust.
-
 Model launches · · 8 min read
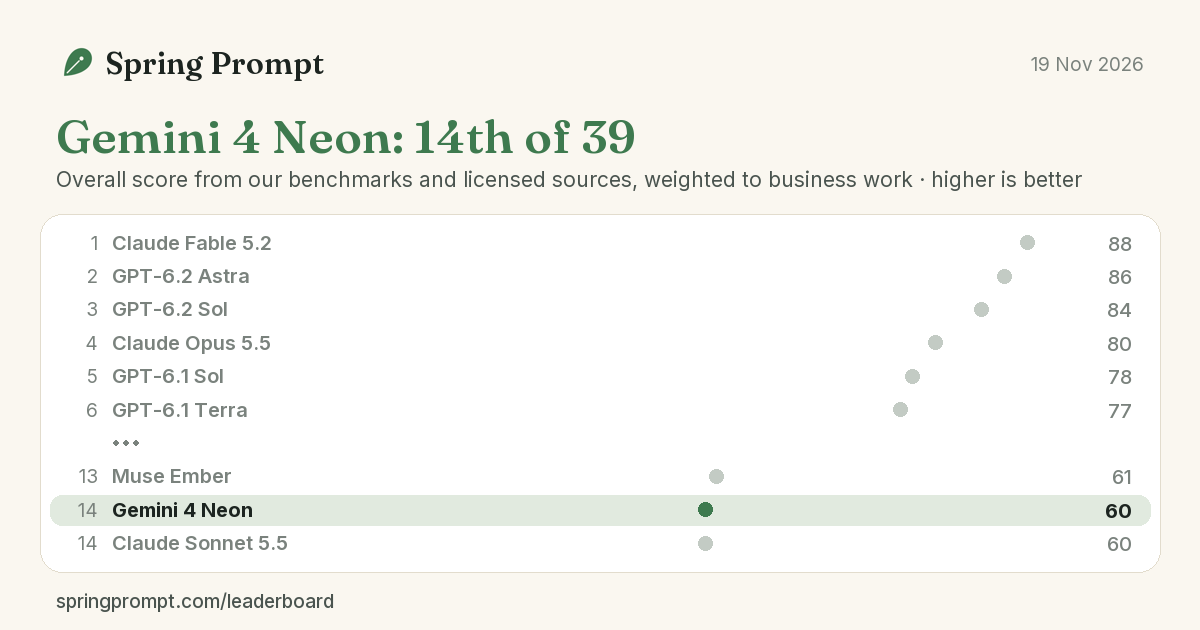
Gemini 4 neon review: The most reliable product listings we've measured
Google's Gemini 4 Neon wrote the most reliable factual product listings of 35 models on our benchmarks, 78.6% publish-ready in every run, ahead of every OpenAI and Anthropic model. It sits between Hydrogen and Carbon on speed for listings, and was weaker on sales copy, slide decks and survey analysis.
-
 Model launches · · 10 min read
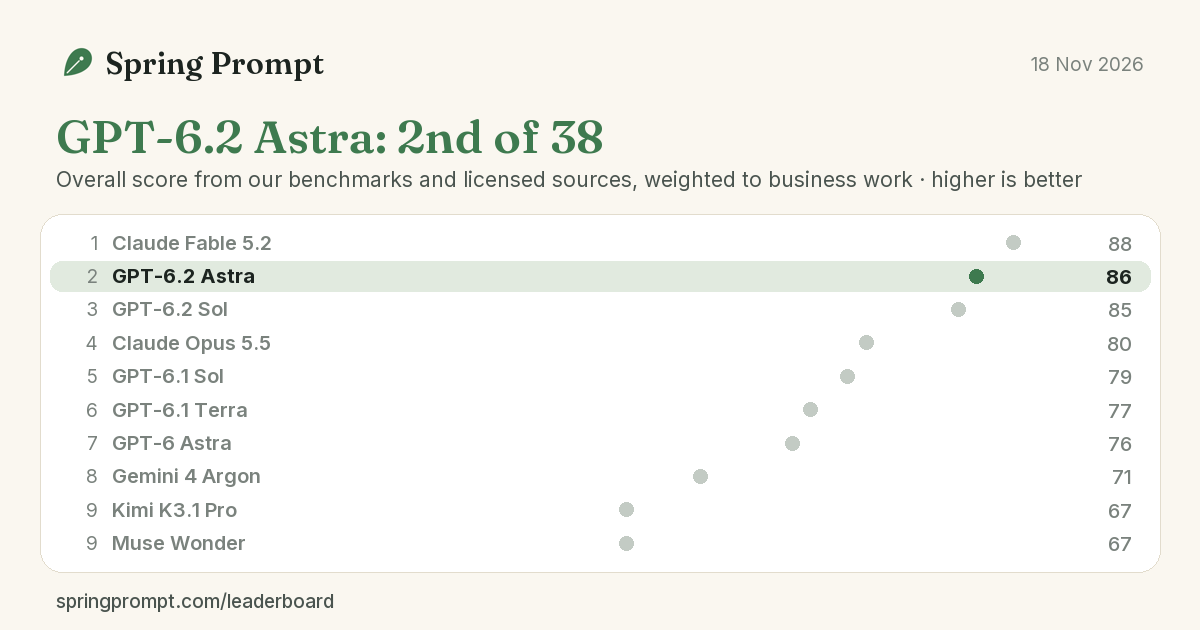
GPT-6.2 review: Sol writes the better listings and decks, Astra the better analysis, at four times the price
We ran OpenAI's GPT-6.2 Sol and GPT-6.2 Astra through our five business benchmarks. Sol wrote the most reliable product listings we have measured and better decks than Astra; Astra was ahead on survey analysis and ad budgets, at four times the token price.
-
 Model launches · · 9 min read
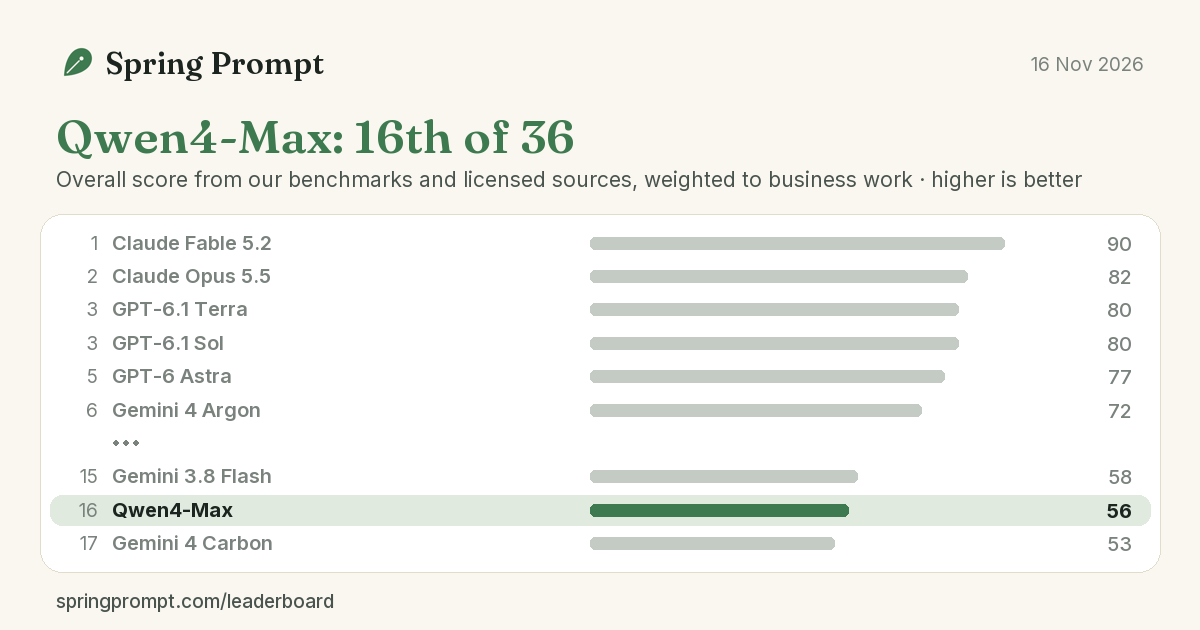
Qwen4-max review: Top of our slide deck ratings, weak on product listings
Alibaba's Qwen4-Max rated first of 32 models on our slide deck benchmark and fifth on survey analysis, at $1.50/$4.50 per million tokens. It was weak on product listings and lost almost every game of speed chess on time.
-
 Model launches · · 8 min read
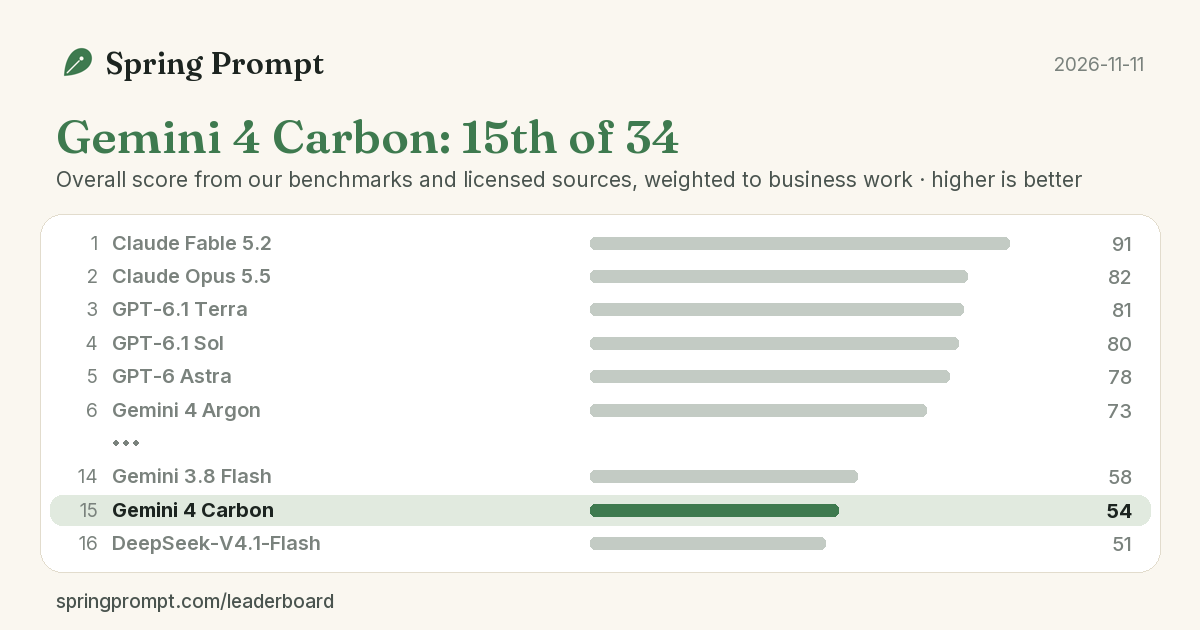
Gemini 4 carbon review: Slower than argon on our business tests
Carbon improved our survey and ad-budget scores, but reliable product listings fell behind Argon. It also took longer and cost more per listing, deck and survey task.
-
 Model launches · · 9 min read
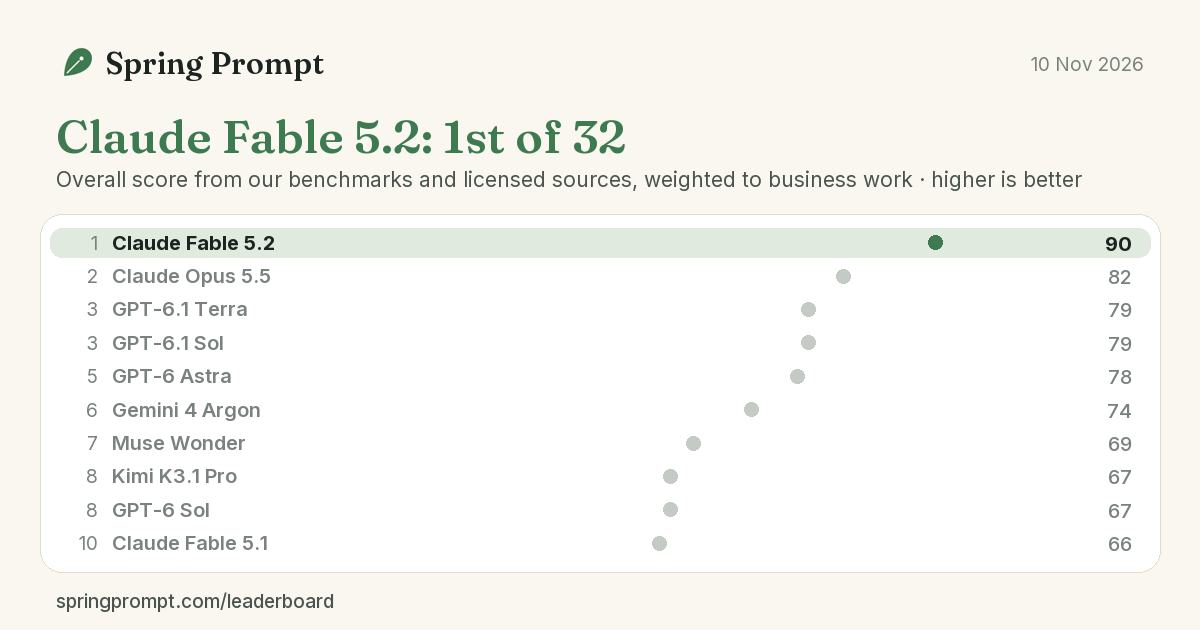
Claude Fable 5.2 review: First on our survey and ad budget tests, and one of the dearest models to run
Claude Fable 5.2 came first on our survey analysis and ad budget benchmarks and third on product listings and slide decks, a large step up from Fable 5.1. It also cost about ten times as much per task as GPT-6.1 Sol.
-
 Model launches · · 9 min read
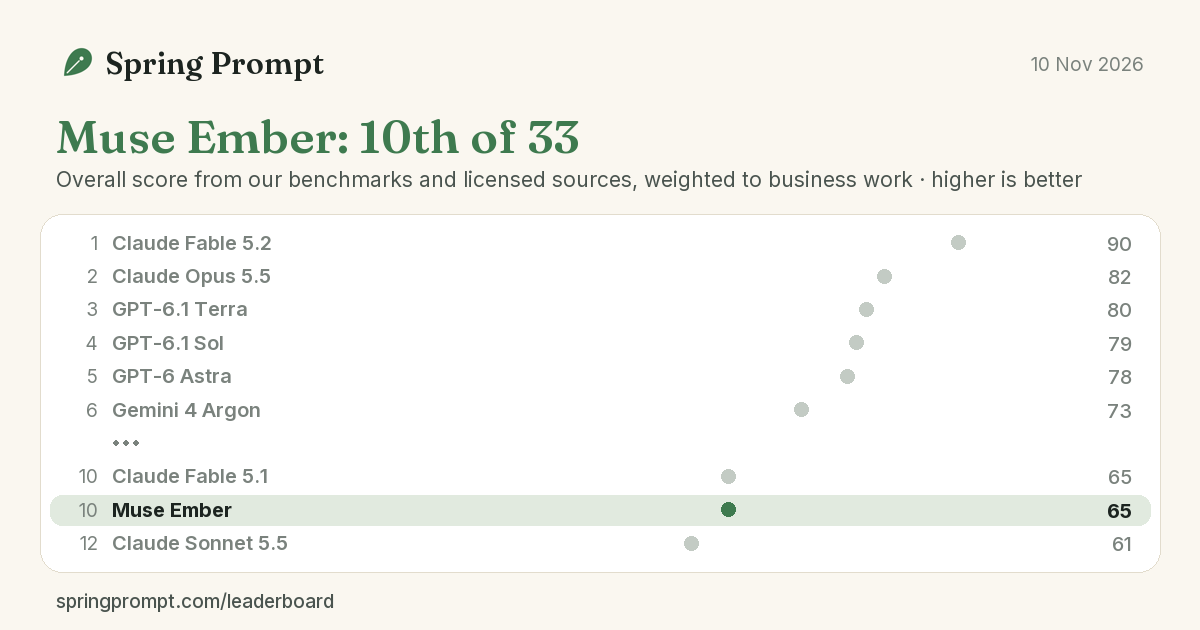
Muse ember review: GPT-6 luna's price, better at analysis, and no Gemini Flash against a clock
Meta's Muse Ember costs the same per token as GPT-6 Luna and Claude Haiku 5.5. On our business benchmarks it landed beside Luna, clearly ahead on survey analysis and behind on sales copy and decks, and it cost up to four times as much per job because it reasons at maximum effort by default.
-
 Model launches · · 8 min read
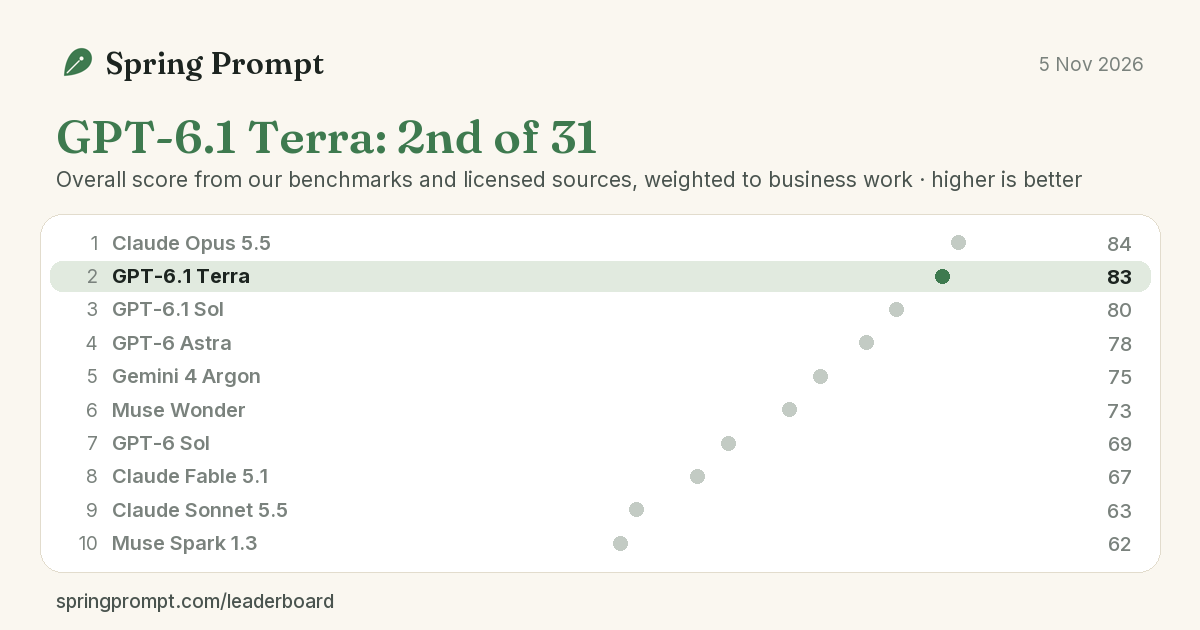
GPT-6.1 terra review: Close to the top of our business tests at half the price of Sol
GPT-6.1 Terra is 2nd on our provisional leaderboard at $1/$5. It set the best ad budget score we have measured and did solid business work, but GPT-6.1 Sol scored higher on decks, surveys and factual listings, and its rank rests on our own benchmarks alone.
-
 Model launches · · 8 min read
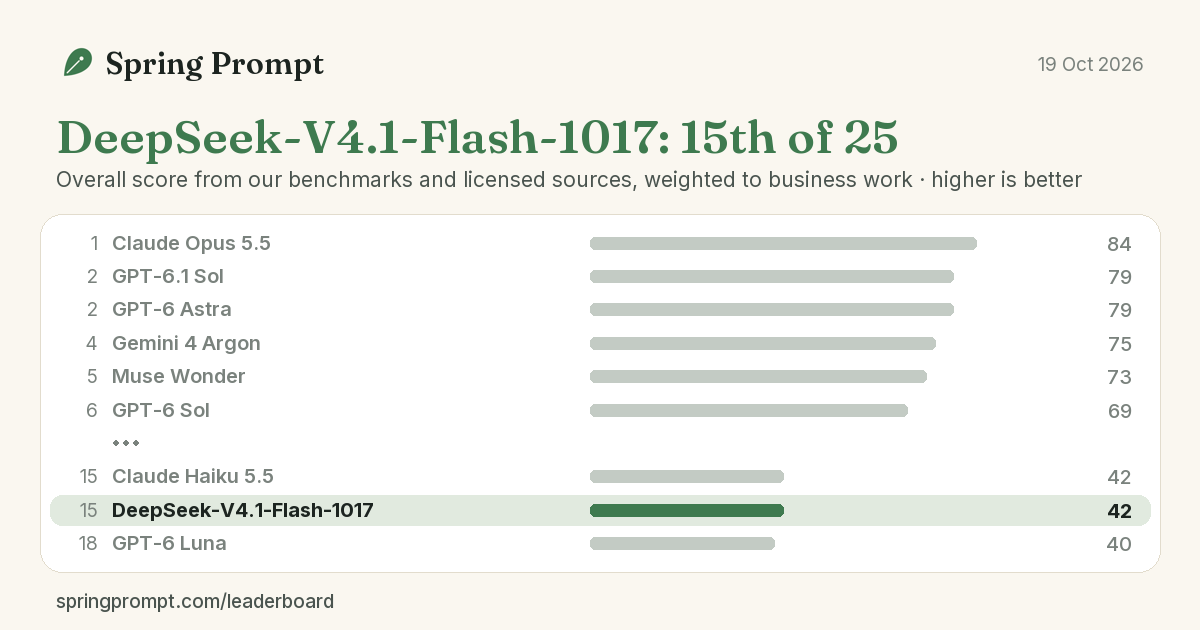
DeepSeek-V4.1-Flash-1017 review: Better at analysis, much worse at sticking to the product data
We ran DeepSeek's 17 October Flash snapshot through six benchmarks two days after launch. Its surveys and slide decks improved a lot, but its product listings were reliably publishable half as often, because it added three times as many claims the data didn't support.
-
 Model launches · · 6 min read
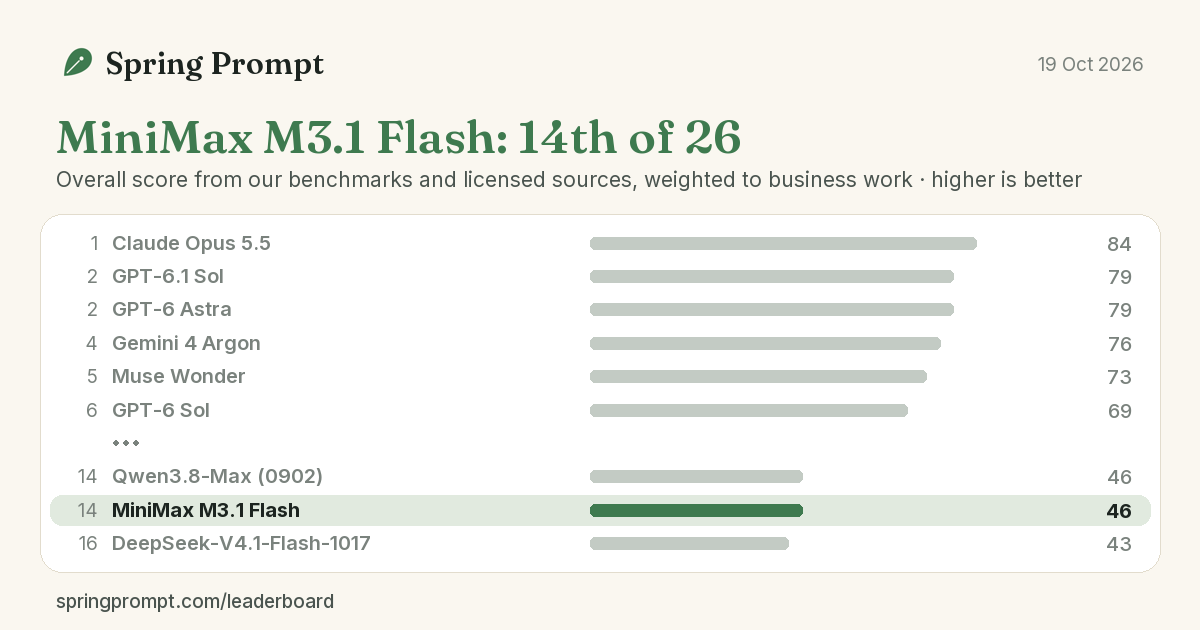
MiniMax M3.1 Flash first look: Careful with product data, unreliable on long jobs
We ran MiniMax M3.1 Flash through six benchmarks on launch day, on OpenRouter's free route. It wrote some of the most reliable product listings of any cheap model, then ran out of room thinking on half our survey tasks.
-
 Model launches · · 8 min read
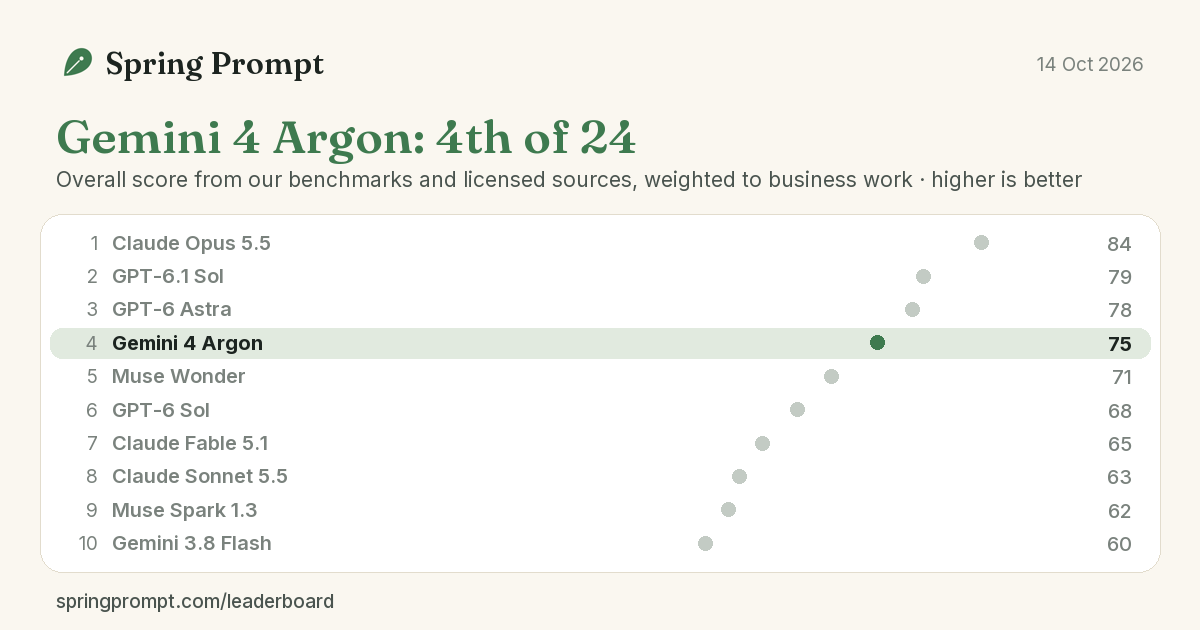
Gemini 4 argon review: Opus-level product data at a quarter of the cost, until you ask it to sell
We ran Gemini 4 Argon through six benchmarks on launch day. It matched Claude Opus 5.5 on product data at a quarter of the cost, then added five times as many unsupported claims when asked to sell.
-
 Model launches · · 7 min read
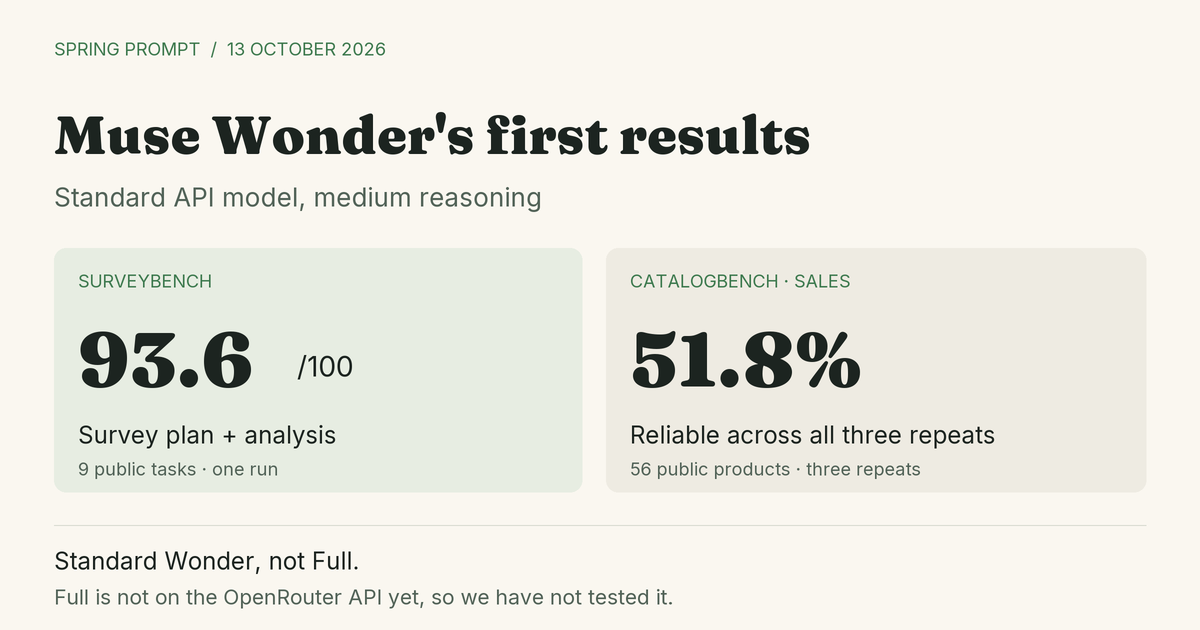
Muse wonder review: Good analysis, work that still needs checking
We tested standard Muse Wonder on six evaluations. Survey analysis was strong; product copy, slide layout and decisions against a clock still needed work. Full is outside this API comparison.
-
 Model launches · · 8 min read
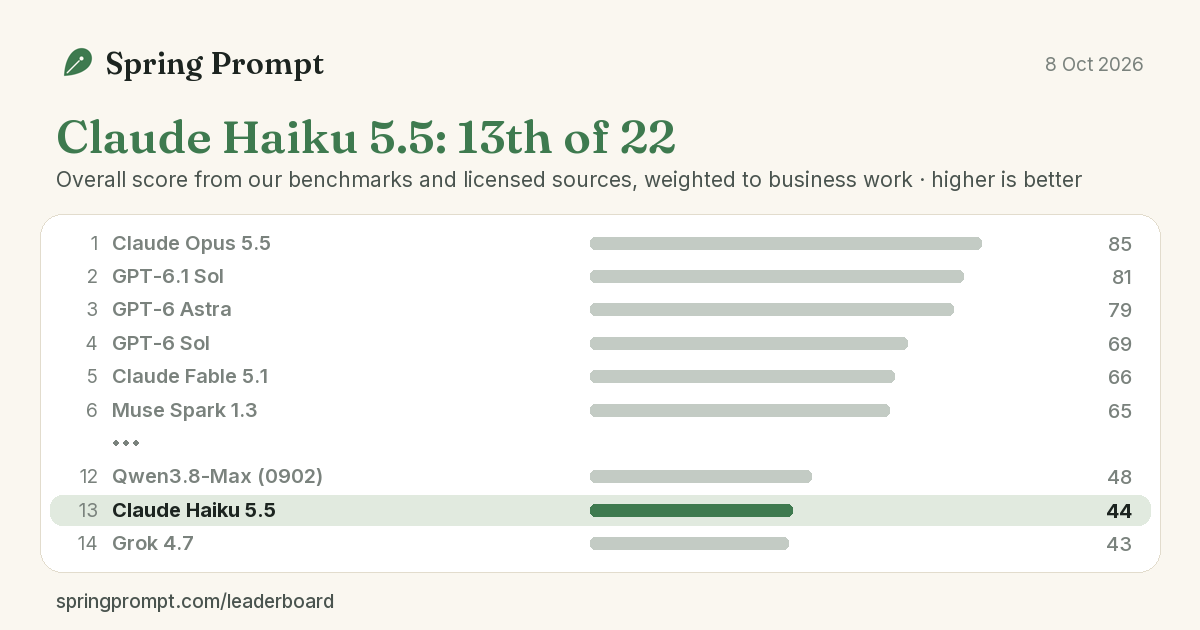
Claude Haiku 5.5 is far better than Haiku 4.5 at a tenth of the price. GPT-6 Luna still beats it at business work
We ran Claude Haiku 5.5 through our business benchmarks and 18 playground tests on launch day. It is a big step up from Haiku 4.5 and very cheap, but GPT-6 Luna, at the same price, beat it on listings, decks and ad planning.
-
 Model launches · · 7 min read
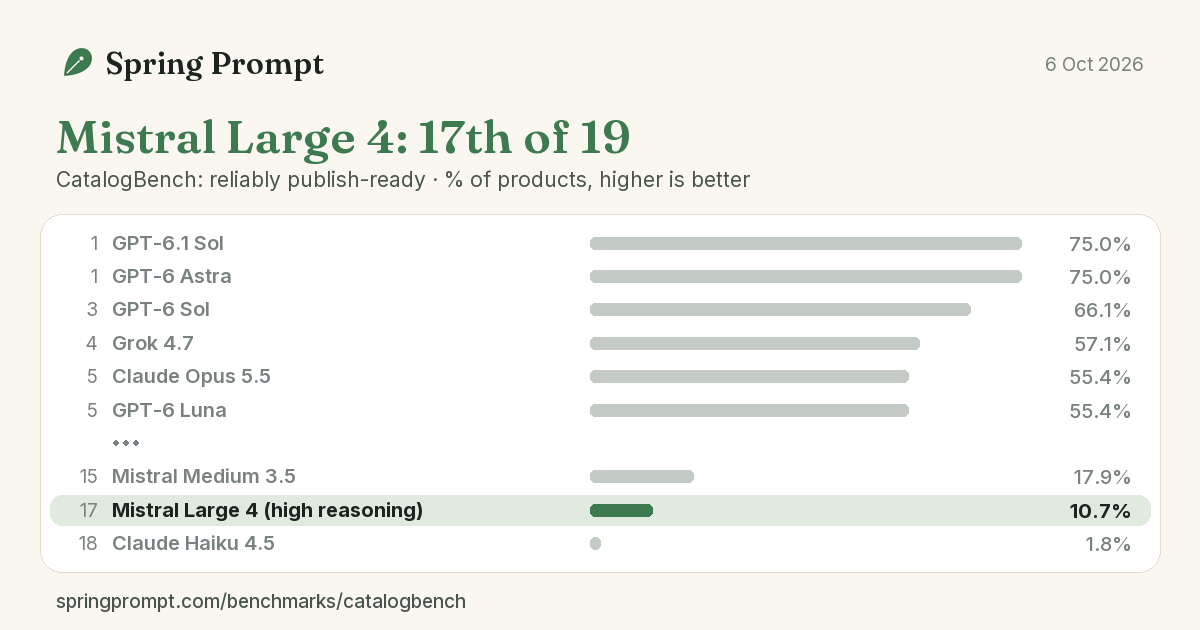
Mistral Large 4 is fast, cheap and Europe's best model. On business work, it still makes things up.
We ran Mistral Large 4 through our four business benchmarks on launch day. It is quick, inexpensive and careful with structured data, but it added unsupported claims to most product listings and finished last on slide decks.