
Compare / Gemini 3.1 Pro Preview vs Gemini 4 Argon
Gemini 3.1 Pro Preview vs Gemini 4 Argon
Which is cheaper, which is more capable, and which does better at each kind of work, from 103 results on 7 sources that measured both models.

Of the 103 results both models have, the better value on each. Results whose reported ranges overlap are too close to call.
Results as of 19 November 2026 (catalogue release 2026-11-19-3608133e8331).
Gemini 3.1 Pro Preview or Gemini 4 Argon? The short answer
Pick Gemini 4 Argon: it scores higher (Spring Prompt overall 70 against 44) and costs less.
- Spring Prompt overall: Gemini 3.1 Pro Preview 44, Gemini 4 Argon 70 (out of 100; how the score works).
- Gemini 4 Argon is cheaper to run: $0.011 against $0.035 per product listing on CatalogBench (3.2 times less).
- Gemini 4 Argon scores higher on the Artificial Analysis Intelligence Index: 52.6 against 29.7.
- Gemini 4 Argon is newer: released 13 Oct 2026, against 19 Feb 2026 for Gemini 3.1 Pro Preview.
- On our own benchmarks, on the results both models have: Gemini 4 Argon does better for product listings, decks from an analysis, user surveys and marketing planning.
- On third-party benchmarks, on the results both models have: Gemini 4 Argon does better for agents and tool use, reasoning and knowledge, writing and sticking to the facts.
Head to head
Every fact side by side
| Gemini 3.1 Pro Preview | Gemini 4 Argon | |
|---|---|---|
| Price per million tokens | $2.00 in · $12.00 out | $2.00 in · $10.00 out |
| Blended (3 in : 1 out) | $4.50 | $4.00 |
| Cheapest host, blended | $4.50 (Google) | $4.00 (Google) |
| Cost per product listing (CatalogBench) | $0.035 | $0.011 |
| Cached input, per million | $0.20 cached input | – |
| Intelligence Index | 29.7 | 52.6 |
| Spring Prompt overall | 44 | 70 |
| Output speed, tokens a second | 130 | – |
| Context window | 1,048,576 tokens | 1,048,576 tokens |
| Released | 19 Feb 2026 | 13 Oct 2026 (newer) |
| Weights | Closed | Closed |
| Developer based in | the US | the US |
Prices are the developer's list price where we have read it, otherwise the typical host on OpenRouter; see every model's price. Intelligence and speed from Artificial Analysis.
Which is better for what
Each model's rank among the models on sale today, for each kind of work, from our own benchmarks and licensed sources. Further right is better; the better rank is in green.
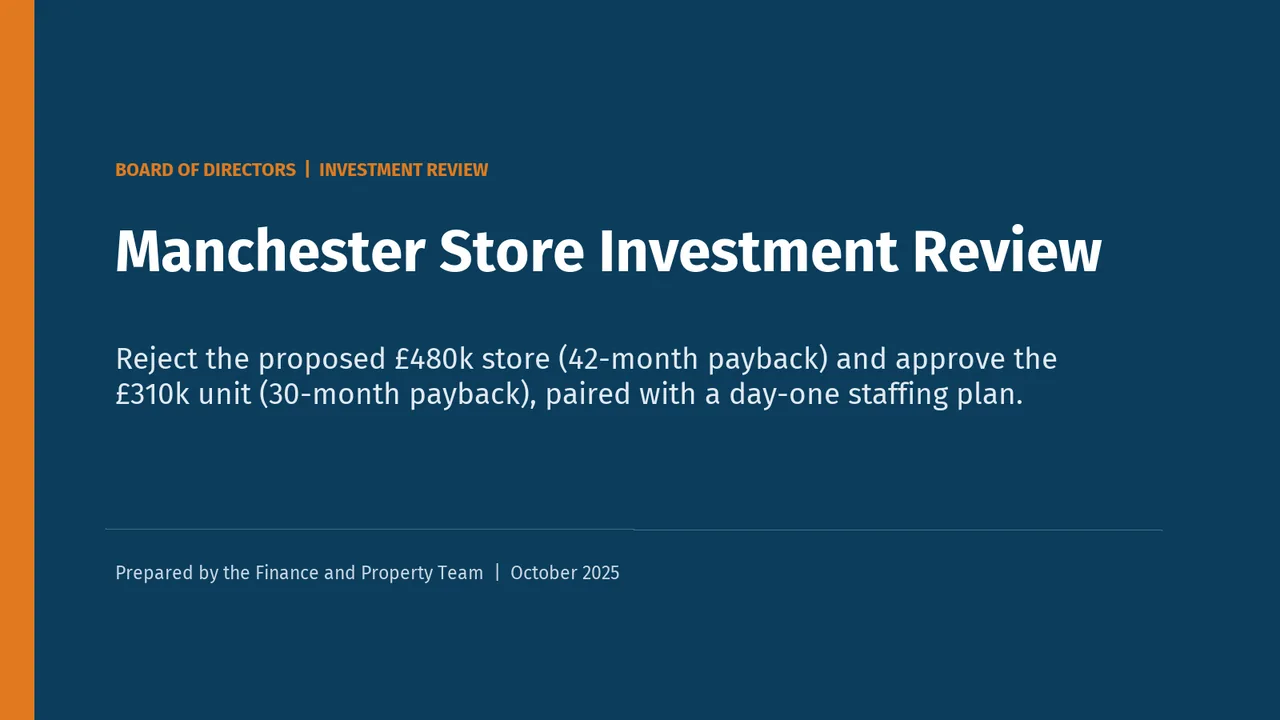
Their slides, side by side
The same brief for both: Manchester store investment review for Hearthside Coffee, an invented company. First slide of each deck from DeckBench.

From our research
- Gemini 4 Argon review: Opus-level product data at a quarter of the cost, until you ask it to sell 14 Oct 2026
- BulletBench: we made 23 AI models play speed chess, and the clock was the judge 3 Jul 2026
- Claude vs Gemini vs GPT in a 12-Month Marketing Simulation 25 Mar 2026
- The AI Marketing Benchmark That Punishes Plausible-Sounding Strategy 20 Mar 2026
Every shared result
Each model's best result on every measure both have, grouped by benchmark, with the setting that produced it. Under each measure, every model that benchmark has measured is a grey tick, best to the right, so you can see where the two sit in the field. The headline measures of each benchmark come first; the rest are under "Show all". Green marks the better value; where a source reports ranges that overlap, neither is marked.
| Measure | Gemini 3.1 Pro Preview | Gemini 4 Argon |
|---|---|---|
| BulletBench measured by Spring Prompt · 3 results | ||
| Cost per game · Blitz 3+2US dollars, lower is better 17 · 13 of 23 measured | $0.21 | $0.12 |
| Cost per game · Bullet 60sUS dollars, lower is better 55 · 29 of 62 measured | $0.0446low reasoning | $0.0036 |
| Ladder Elo · Bullet 60sladder Elo, higher is better 27 · 54 of 62 measured | 529low reasoning | 147 |
| CatalogBench measured by Spring Prompt · 3 results | ||
| Cost per productUS dollars, lower is better 28 · 20 of 36 measured | $0.0355 | $0.0109 |
| Reliably publish-ready% of products, higher is better 19 · 11 of 35 measured | 44.6% | 60.7% |
| Reliably publish-ready · sales brief% of products, higher is better 18 · 17 of 35 measured | 16.1% | 17.9% |
| DeckBench measured by Spring Prompt · 3 results | ||
| Cost per deckUS dollars, lower is better 19 · 18 of 36 measured | $0.14 | $0.11 |
| Deck ratingrating, higher is betterThe rating weighs each win by how strong the other deck was; the win rate counts wins against whichever decks a model happened to meet, so the two can disagree. 31 · 26 of 36 measured | 716 | 951 |
| Accurate decks% of tasks, higher is better 17 · 22 of 36 measured | 50.0% | 33.3% |
| ROASBench measured by Spring Prompt · 3 results | ||
| Overall scorescore out of 100, higher is better 21 · 15 of 36 measured | 43.5 | 47.0 |
| Audience scorescore out of 100, higher is better 12 · 16 of 36 measured | 67.5 | 65.5 |
| Business scorescore out of 100, higher is better 24 · 17 of 36 measured | 35.9 | 43.3 |
| SurveyBench measured by Spring Prompt · 3 results | ||
| Analysis ratingrating, higher is betterThe rating weighs each win by how strong the other analysis was; the win rate counts wins against whichever analyses a model happened to meet, so the two can disagree. 20 · 17 of 27 measured | 744 | 928 |
| Cost per taskUS dollars, lower is better 20 · 16 of 27 measured | $0.33 | $0.13 |
| Analysis scorepoints of 100, higher is better 18 · 15 of 27 measured | 66.4 | 79.6 |
| Arena (formerly LMArena) reported by Arena (formerly LMArena) · 3 results | ||
| Overall · TextArena rating, higher is better 15 · 1 of 387 measured | 1,487 | 1,525high reasoning |
| Overall · Text factualityArena rating, higher is better 21 · 1 of 163 measured | 1,472 | 1,511high reasoning |
| Business, management and finance · TextArena rating, higher is better 23 · 1 of 380 measured | 1,477 | 1,522high reasoning |
| Artificial Analysis reported by Artificial Analysis · 3 results | ||
| Artificial Analysis Intelligence Indexindex score, higher is better 57 · 5 of 249 measured | 29.7 | 52.6high reasoning |
| Humanity's Last Exam% of questions, higher is better 19 · 3 of 250 measured | 47.0% | 57.1%high reasoning |
| Terminal-Bench 4.0% of tasks, higher is better 51 · 5 of 120 measured | 4.0% | 57.1%high reasoning |
Show all 103 results (82 more)
| Measure | Gemini 3.1 Pro Preview | Gemini 4 Argon |
|---|---|---|
| BulletBench measured by Spring Prompt · 7 results | ||
| Games lost on time · Blitz 3+2% of games, lower is better 15 · 1 of 23 measured | 50.0% | 0.0% |
| Games lost on time · Bullet 60s% of games, lower is better 45 · 57 of 62 measured | 58.3%low reasoning | 87.5% |
| Invalid moves · Blitz 3+2% of moves, lower is better 1 · 1 of 23 measured | 0.0% | 0.0% |
| Invalid moves · Bullet 60s% of moves, lower is better 1 · 1 of 62 measured | 0.0%low reasoning | 0.0% |
| Ladder Elo · Blitz 3+2ladder Elo, higher is better 12 · 1 of 23 measured | 683 | 1,147 |
| Median move time · Blitz 3+2milliseconds, lower is better 17 · 5 of 23 measured | 6.2 s | 1.9 s |
| Median move time · Bullet 60smilliseconds, lower is better 57 · 54 of 62 measured | 3.1 slow reasoning | 2.9 s |
| CatalogBench measured by Spring Prompt · 28 results | ||
| Channel compliance% of products, higher is better 28 · 1 of 36 measured | 99.4% | 100.0% |
| Channel rules broken% of products, lower is better 22 · 1 of 36 measured | 0.6% | 0.0% |
| Channel rules broken · sales brief% of products, lower is better 1 · 1 of 36 measured | 0.0% | 0.0% |
| Claims to check% of products, lower is better 28 · 1 of 34 measured | 1.2% | 0.0% |
| Claims to check · sales brief% of products, lower is better 31 · 1 of 34 measured | 10.1% | 0.0% |
| Conflicts caught% of conflicts, higher is better 1 · 1 of 36 measured | 100.0% | 100.0% |
| Content quality% of checks, higher is better 21 · 8 of 36 measured | 96.9% | 98.2% |
| Content quality · sales brief% of checks, higher is better 20 · 8 of 36 measured | 97.2% | 98.4% |
| Decision accuracy% of decisions, higher is better 20 · 10 of 36 measured | 96.6% | 97.8% |
| Failed outputs% of products, lower is better 1 · 1 of 36 measured | 0.0% | 0.0% |
| Failed outputs · sales brief% of products, lower is better 1 · 1 of 36 measured | 0.0% | 0.0% |
| Field accuracy% of missing fields, higher is better 4 · 8 of 36 measured | 95.4% | 94.7% |
| Invented values% of filled values, lower is better 17 · 21 of 36 measured | 1.5% | 1.7% |
| Missing UK information% of products, lower is better 1 · 1 of 36 measured | 0.0% | 0.0% |
| Missing UK information · sales brief% of products, lower is better 1 · 1 of 36 measured | 0.0% | 0.0% |
| Not findable% of products, lower is better 27 · 9 of 36 measured | 7.7% | 2.4% |
| Not findable · sales brief% of products, lower is better 26 · 5 of 36 measured | 6.0% | 1.8% |
| Publish-ready listings% of products, higher is better 22 · 13 of 36 measured | 58.9% | 70.8% |
| Publish-ready listings · sales brief% of products, higher is better 21 · 17 of 36 measured | 30.4% | 35.1% |
| Time per productseconds, lower is better 25 · 5 of 36 measured | 22.2 | 7.30 |
| Unsupported claimsclaims per product, lower is better 21 · 16 of 36 measured | 0.66 | 0.42 |
| Unsupported claims% of products, lower is better 24 · 18 of 36 measured | 26.8% | 16.1% |
| Unsupported claims · sales briefclaims per product, lower is better 23 · 21 of 36 measured | 2.13 | 1.98 |
| Unsupported claims · sales brief% of products, lower is better 24 · 22 of 36 measured | 67.3% | 63.1% |
| Wrong attributes% of products, lower is better 12 · 14 of 36 measured | 14.9% | 15.5% |
| Wrong attributes · sales brief% of products, lower is better 18 · 15 of 36 measured | 16.1% | 15.5% |
| Wrong category or variant% of products, lower is better 7 · 7 of 36 measured | 1.8% | 1.8% |
| Wrong category or variant · sales brief% of products, lower is better 7 · 7 of 36 measured | 1.8% | 1.8% |
| DeckBench measured by Spring Prompt · 14 results | ||
| Caveat dropped% of tasks, lower is better 16 · 1 of 36 measured | 16.7% | 0.0% |
| Clean layout% of tasks, higher is better 16 · 18 of 36 measured | 50.0% | 33.3% |
| Design quality% of the maximum, higher is better 30 · 28 of 36 measured | 51.4% | 55.2% |
| Draft figure quoted% of tasks, lower is better 1 · 29 of 36 measured | 0.0% | 50.0% |
| Findings missing% of tasks, lower is better 1 · 1 of 36 measured | 0.0% | 0.0% |
| Head-to-head win rate% of comparisons, higher is betterThe rating weighs each win by how strong the other deck was; the win rate counts wins against whichever decks a model happened to meet, so the two can disagree. 31 · 19 of 36 measured | 31.2% | 51.4% |
| Layout defects% of tasks, lower is better 16 · 18 of 36 measured | 50.0% | 66.7% |
| Misleading metric used% of tasks, lower is better 1 · 1 of 36 measured | 0.0% | 0.0% |
| Presentable decks% of tasks, higher is better 14 · 17 of 36 measured | 16.7% | 0.0% |
| Recommendation late or wrong% of tasks, lower is better 28 · 1 of 36 measured | 50.0% | 0.0% |
| Slides needing work% of tasks, lower is better 34 · 26 of 36 measured | 83.3% | 66.7% |
| Time per deckseconds, lower is better 10 · 8 of 36 measured | 78.0 | 67.5 |
| Unsupported claims% of tasks, lower is better 1 · 17 of 36 measured | 0.0% | 16.7% |
| Unsupported numbers% of tasks, lower is better 1 · 1 of 36 measured | 0.0% | 0.0% |
| ROASBench measured by Spring Prompt · 6 results | ||
| Consistency scorescore out of 100, higher is better 12 · 11 of 36 measured | 33.9 | 34.7 |
| Contribution profitsimulated US dollars, higher is better 24 · 15 of 36 measured | $507,736 | $673,561 |
| Cost of a runUS dollars, lower is better 24 · 19 of 36 measured | $0.52 | $0.24 |
| Months over budgetmonths of 12, lower is better 1 · 1 of 36 measured | 0 | 0 |
| Planning scorescore out of 100, higher is better 15 · 1 of 36 measured | 54.9 | 55.4 |
| Return on ad spendprofit per $1 spent, higher is better 25 · 16 of 36 measured | $0.42 | $0.55 |
| SurveyBench measured by Spring Prompt · 17 results | ||
| Head-to-head win rate% of comparisons, higher is betterThe rating weighs each win by how strong the other analysis was; the win rate counts wins against whichever analyses a model happened to meet, so the two can disagree. 22 · 19 of 27 measured | 33.1% | 40.2% |
| Leading or double-barrelled questions% of tasks, lower is better 15 · 24 of 27 measured | 44.4% | 66.7% |
| Mistaken next steps% of tasks, lower is better 18 · 18 of 27 measured | 33.3% | 33.3% |
| Numbers right% of answers, higher is better 1 · 22 of 27 measured | 100.0% | 97.1% |
| Objectives unanswerable% of tasks, lower is better 1 · 1 of 27 measured | 0.0% | 0.0% |
| Precision ignored% of tasks, lower is better 23 · 16 of 27 measured | 55.6% | 11.1% |
| Research scorepoints of 100, higher is better 18 · 16 of 27 measured | 71.3 | 83.3 |
| Sound research% of tasks, higher is better 17 · 17 of 27 measured | 0.0% | 0.0% |
| Stakeholder's view presumed% of tasks, lower is better 18 · 12 of 27 measured | 22.2% | 11.1% |
| Survey plan scorepoints of 100, higher is better 23 · 17 of 27 measured | 82.9 | 91.8 |
| Survey structure% of tasks, lower is better 12 · 1 of 27 measured | 22.2% | 0.0% |
| Time per taskseconds, lower is better 14 · 4 of 27 measured | 170 | 74.4 |
| Traps handled% of traps, higher is better 23 · 18 of 27 measured | 71.0% | 84.1% |
| Traps missed% of tasks, lower is better 19 · 17 of 27 measured | 88.9% | 77.8% |
| Unsupported findings% of tasks, lower is better 16 · 22 of 27 measured | 77.8% | 88.9% |
| Wrong numbers% of tasks, lower is better 1 · 19 of 27 measured | 0.0% | 33.3% |
| Wrong recommendation% of tasks, lower is better 19 · 5 of 27 measured | 44.4% | 11.1% |
| Arena (formerly LMArena) reported by Arena (formerly LMArena) · 8 results | ||
| Confirmed task success · AgentIPS effect estimate, higher is better 42 · 3 of 48 measured | -0.10arena agent | 0.15high reasoning, arena agent |
| Creative writing · TextArena rating, higher is better 10 · 1 of 385 measured | 1,480 | 1,519high reasoning |
| Expert prompts · TextArena rating, higher is better 26 · 7 of 338 measured | 1,509 | 1,539high reasoning |
| Instruction following · TextArena rating, higher is better 17 · 1 of 387 measured | 1,480 | 1,528high reasoning |
| Praise over complaint · AgentIPS effect estimate, higher is better 29 · 4 of 48 measured | -0.01arena agent | 0.28high reasoning, arena agent |
| Steerability · AgentIPS effect estimate, higher is better 37 · 1 of 48 measured | -0.05arena agent | 0.13high reasoning, arena agent |
| Tool grounding · AgentIPS effect estimate, higher is better 35 · 29 of 48 measured | -0.00arena agent | 0.00high reasoning, arena agent |
| Writing, literature and language · TextArena rating, higher is better 11 · 1 of 386 measured | 1,480 | 1,522high reasoning |
| Artificial Analysis reported by Artificial Analysis · 2 results | ||
| Long-context reasoning (AA-LCR)% of questions, higher is better 27 · 47 of 241 measured | 82.0% | 79.7%high reasoning |
| SciCode% of problems, higher is better 14 · 3 of 121 measured | 58.7% | 61.8%high reasoning |
Compare them with other models
- Gemini 3.1 Pro Preview vs Claude Opus 5.5Most intelligent at $3–10 per million tokens
- Gemini 3.1 Pro Preview vs GPT-6.2 SolHighest-scoring overall at $3–10 per million tokens
- Gemini 3.1 Pro Preview vs Claude Fable 5.2Highest-scoring overall available today
- Gemini 4 Argon vs Claude Opus 5.5Most intelligent at $3–10 per million tokens
- Gemini 4 Argon vs GPT-6.2 SolHighest-scoring overall at $3–10 per million tokens
- Gemini 4 Argon vs Claude Fable 5.2Highest-scoring overall available today
Quick answers
Is Gemini 3.1 Pro Preview better than Gemini 4 Argon?
Pick Gemini 4 Argon: it scores higher (Spring Prompt overall 70 against 44) and costs less.
Which is cheaper, Gemini 3.1 Pro Preview or Gemini 4 Argon?
Gemini 4 Argon is cheaper to run: $0.011 against $0.035 per product listing on CatalogBench (3.2 times less).
Which is better for product listings, Gemini 3.1 Pro Preview or Gemini 4 Argon?
Gemini 4 Argon ranks 15 of 35 models on sale for turning a sparse product feed and photos into listings that can go live, against 19 for Gemini 3.1 Pro Preview.
Which is better for decks from an analysis, Gemini 3.1 Pro Preview or Gemini 4 Argon?
Gemini 4 Argon ranks 26 of 35 models on sale for turning a finished analysis into a deck you could present as it is, against 30 for Gemini 3.1 Pro Preview.
Which is better for user surveys, Gemini 3.1 Pro Preview or Gemini 4 Argon?
Gemini 4 Argon ranks 17 of 26 models on sale for planning a user survey and reading its results without being misled, against 20 for Gemini 3.1 Pro Preview.
Which is better for marketing planning, Gemini 3.1 Pro Preview or Gemini 4 Argon?
Gemini 4 Argon ranks 15 of 35 models on sale for planning a year of ad spend without overspending, against 21 for Gemini 3.1 Pro Preview.
Which is better for agents and tool use, Gemini 3.1 Pro Preview or Gemini 4 Argon?
Gemini 4 Argon ranks 5 of 159 models on sale for multi-step tasks with tools: support desks, coding agents, function calls, against 66 for Gemini 3.1 Pro Preview.
Run Gemini 3.1 Pro Preview and Gemini 4 Argon on your own prompt.
Benchmarks aren't your task. Test both side by side on your prompt, with every answer checked against your rules and the cost of each one.