
Leaderboard / Spring Prompt Score

Measured by Spring Prompt

Spring Prompt Score

One number per model from our own benchmarks only: CatalogBench, DeckBench, SurveyBench, ROASBench and BulletBench. Every benchmark counts the same (what each one tests). Because it uses no third-party results, you are free to cite it, download it and embed it.

Models scored
35
Benchmarks
5, all ours
Results up to
19 Nov 2026
Score
0–100, higher is better
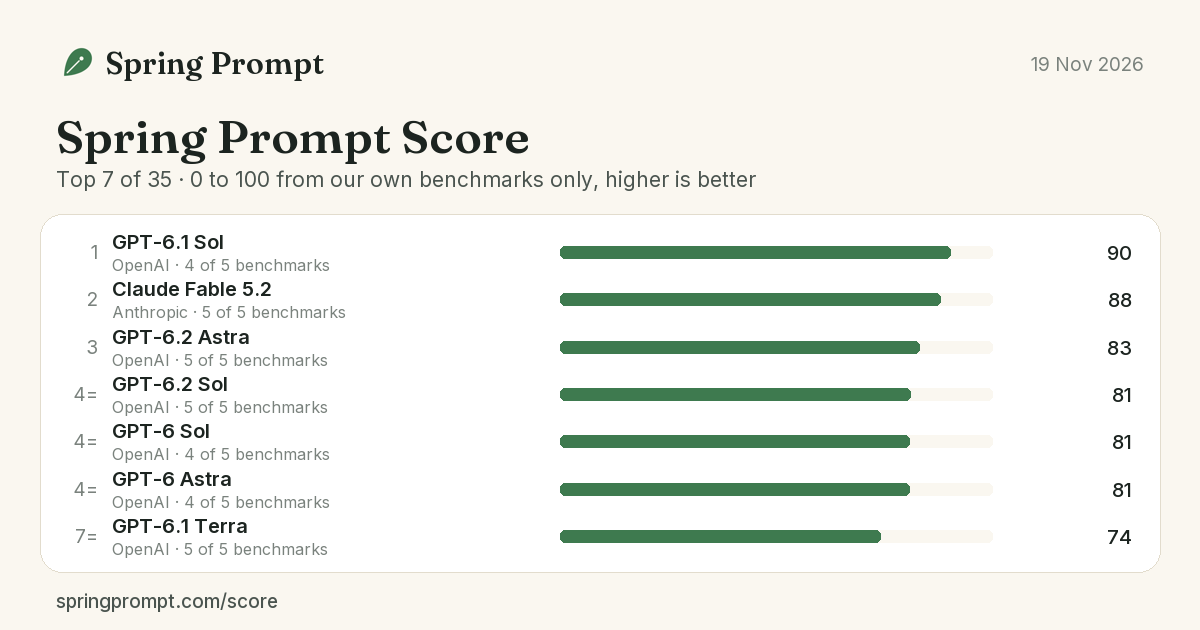
Spring Prompt Score from 0 to 100, higher is better, with how many of our benchmarks it covers and the model's percentile on each
#ModelScoreCoveragePercentile on each benchmark
1 GPT-6.1 SolOpenAI 90 4 of 5 benchmarks CatalogBench 91DeckBench 89SurveyBench 88ROASBench –BulletBench 93
2 Claude Fable 5.2Anthropic 88 5 of 5 benchmarks CatalogBench 81DeckBench 91SurveyBench 100ROASBench 100BulletBench 68
3 GPT-6.2 AstraOpenAI 83 5 of 5 benchmarks CatalogBench 92DeckBench 54SurveyBench 96ROASBench 94BulletBench 79
4= GPT-6.2 SolOpenAI 81 5 of 5 benchmarks CatalogBench 97DeckBench 86SurveyBench 77ROASBench 77BulletBench 68
4= GPT-6 SolOpenAI 81 4 of 5 benchmarks CatalogBench 85DeckBench 94SurveyBench –ROASBench 86BulletBench 59
4= GPT-6 AstraOpenAI 81 4 of 5 benchmarks CatalogBench 95DeckBench 97SurveyBench –ROASBench 91BulletBench 39
7= GPT-6.1 TerraOpenAI 74 5 of 5 benchmarks CatalogBench 82DeckBench 77SurveyBench 65ROASBench 97BulletBench 48
7= Claude Opus 5.5Anthropic 74 4 of 5 benchmarks CatalogBench 60DeckBench 80SurveyBench 85ROASBench 71BulletBench –
9 Muse WonderMeta 64 5 of 5 benchmarks CatalogBench 81DeckBench 60SurveyBench 92ROASBench 31BulletBench 54
10= GPT-6 LunaOpenAI 60 5 of 5 benchmarks CatalogBench 72DeckBench 69SurveyBench 50ROASBench 83BulletBench 29
10= Gemini 4 HydrogenGoogle 60 5 of 5 benchmarks CatalogBench 67DeckBench 43SurveyBench 54ROASBench 49BulletBench 86
12 Muse EmberMeta 59 5 of 5 benchmarks CatalogBench 64DeckBench 51SurveyBench 73ROASBench 74BulletBench 34
13 Qwen4-MaxAlibaba 57 5 of 5 benchmarks CatalogBench 35DeckBench 100SurveyBench 81ROASBench 51BulletBench 20
14 Claude Fable 5.1Anthropic 56 3 of 5 benchmarks CatalogBench 27DeckBench 71SurveyBench –ROASBench 69BulletBench –
15 Gemini 4 NeonGoogle 55 5 of 5 benchmarks CatalogBench 82DeckBench 34SurveyBench 15ROASBench 57BulletBench 86
16 Grok 4.7xAI 53 3 of 5 benchmarks CatalogBench 68DeckBench 66SurveyBench –ROASBench 26BulletBench –
17 Claude Sonnet 5.5Anthropic 51 4 of 5 benchmarks CatalogBench 36DeckBench 83SurveyBench –ROASBench 80BulletBench 5
18 Gemini 4 CarbonGoogle 48 5 of 5 benchmarks CatalogBench 52DeckBench 31SurveyBench 46ROASBench 63BulletBench 46
19 Kimi K3.1 ProMoonshot AI 46 4 of 5 benchmarks CatalogBench –DeckBench 63SurveyBench 12ROASBench 89BulletBench 20
20= Gemini 3.8 FlashGoogle 42 5 of 5 benchmarks CatalogBench 30DeckBench 20SurveyBench 35ROASBench 66BulletBench 60
20= Gemini 4 ArgonGoogle 42 5 of 5 benchmarks CatalogBench 62DeckBench 29SurveyBench 38ROASBench 60BulletBench 20
20= Gemini 3.1 Pro PreviewGoogle 42 5 of 5 benchmarks CatalogBench 49DeckBench 14SurveyBench 27ROASBench 43BulletBench 75
23= Claude Haiku 5.5Anthropic 38 5 of 5 benchmarks CatalogBench 32DeckBench 49SurveyBench 69ROASBench 6BulletBench 34
23= Particle-1Particle AI 38 4 of 5 benchmarks CatalogBench 4DeckBench 46SurveyBench 62ROASBench 40BulletBench –
25 MiniMax M3.1 FlashMiniMax 37 5 of 5 benchmarks CatalogBench 63DeckBench 74SurveyBench 0ROASBench 34BulletBench 11
26= Kimi K3Moonshot AI 34 4 of 5 benchmarks CatalogBench 31DeckBench 57SurveyBench –ROASBench 46BulletBench 4
26= DeepSeek-V4.1-Flash-1017DeepSeek 34 5 of 5 benchmarks CatalogBench 14DeckBench 40SurveyBench 58ROASBench 37BulletBench 20
29 Mercury 3Inception 32 4 of 5 benchmarks CatalogBench –DeckBench 17SurveyBench 23ROASBench 17BulletBench 69
30 Gemini 3.5 Flash-LiteGoogle 31 5 of 5 benchmarks CatalogBench 21DeckBench 9SurveyBench 19ROASBench 11BulletBench 95
31 Muse Spark 1.3Meta 24 4 of 5 benchmarks CatalogBench 45DeckBench 23SurveyBench –ROASBench 23BulletBench 4
32 Qwen3.8-Max (0902)Alibaba 23 3 of 5 benchmarks CatalogBench 18DeckBench 37SurveyBench –ROASBench 14BulletBench –
33= Mistral Large 4Mistral AI 22 5 of 5 benchmarks CatalogBench 15DeckBench 6SurveyBench 31ROASBench 29BulletBench 30
33= Mistral Medium 3.5Mistral AI 22 5 of 5 benchmarks CatalogBench 28DeckBench 3SurveyBench 8ROASBench 0BulletBench 71
35 Claude Haiku 4.5Anthropic 11 5 of 5 benchmarks CatalogBench 7DeckBench 11SurveyBench 4ROASBench 3BulletBench 32

Not scored yet, with results on fewer than 3 of our benchmarks: DeepSeek-V4-Pro (0423), DeepSeek-V4.1-Flash, GLM-5.3, GLM-5V-Turbo.

How the score works

  1. Percentiles, not raw scores. On each benchmark's headline measure a model scores the share of the other models it beats, from 0 to 100 (ties count half), so a share of products and a chess rating can be averaged. Where a model was run in more than one configuration, such as different reasoning efforts, its best result counts. CatalogBench's two briefs and BulletBench's two clocks are averaged into one percentile each.
  2. The same field of models. Models are compared with the models we tested on CatalogBench or ROASBench, the same field as the overall leaderboard.
  3. Equal weights. The score is the plain average of the percentiles a model has. It needs results on at least 3 of our 5 benchmarks; the coverage column says how many.
  4. What it does not cover. Our benchmarks test business work: product listings, slide decks, survey analysis, ad budgets and fast decisions under time pressure. They do not test coding, agents and tool use, factual knowledge or general chat. A missing benchmark is left out rather than counted as zero, so a model with fewer benchmarks can rank higher than one tested on all of them. Differences of a few points are within noise.

How it differs from the overall leaderboard

The overall leaderboard blends our benchmarks with licensed results from other leaderboards, such as Artificial Analysis and LMArena, weighted towards business work. It covers more ground, but those results are not ours to republish. The Spring Prompt Score uses only results we measured ourselves, so it is open data under CC BY 4.0 and every model can show it as a badge.

Download it as score.csv or score.json from our open data. Each model page has the code to embed its badge, and you can embed this chart. More on the method in our methodology.
Embed this chart

Put Spring Prompt Score's current top 10 in your article. Free to reuse under CC BY 4.0; the code includes the credit link. Add ?n=5 for fewer rows, ?models= with model slugs (as in our model page addresses) for your own comparison, or ?theme=dark.

Interactive chart

<iframe src="https://springprompt.com/embed/score" title="Spring Prompt Score results by Spring Prompt" width="100%" height="456" style="border:0;max-width:720px" loading="lazy"></iframe>
<p><a href="https://springprompt.com/score">Spring Prompt Score results by Spring Prompt</a></p>

Image, for sites that block iframes

<a href="https://springprompt.com/score"><img src="https://springprompt.com/og/score.png" alt="Spring Prompt Score: the top 7 AI models by score" width="1200" height="630" style="max-width:100%;height:auto"></a>
<p><a href="https://springprompt.com/score">Spring Prompt Score results by Spring Prompt</a></p>
See the image