Benchmarks / CatalogBench

Measured by Spring Prompt

CatalogBench

Which models can turn a sparse product feed, product photos and supplier copy into a listing that could go live, without inventing anything?

Results dated
30 Sep 2026
Models
18
Unit
US dollars
Licence
Spring Prompt original
Judge
openai/gpt-6.1-sol
Runs
3 per model

Ask for copy that sells, and accuracy drops

Each model's share of products that were publish-ready in all three runs, under the factual brief and under the sales brief.

Factual briefSales brief
GPT-6 Astra
75.0% · 67.9%
GPT-6.1 Sol
73.2% · 67.9%
GPT-6 Sol
62.5% · 64.3%
Claude Opus 5.5
58.9% · 17.9%
GPT-6 Luna
55.4% · 55.4%
Grok 4.7
53.6% · 37.5%
Muse Spark 1.3
46.4% · 19.6%
DeepSeek V4.1 Flash
44.6% · 21.4%
Gemini 3.1 Pro Preview
41.1% · 10.7%
Kimi K3
41.1% · 1.8%
Gemini 3.8 Flash
37.5% · 3.6%
Qwen3.8 Max (0902)
33.9% · 1.8%
Claude Sonnet 5.5
32.1% · 12.5%
Claude Fable 5.1
26.8% · 1.8%
Mistral Medium 3.5
19.6% · 7.1%
Gemini 3.5 Flash Lite
16.1% · 3.6%
Claude Haiku 4.5
1.8% · 0.0%
GLM 5V Turbo
0.0% · 0.0%

Full results

CatalogBench: cost per product, US dollars, lower is better
#ModelCatalogBench: cost per product
US dollars, lower is better
Publish-ready, factual brief
% of products
Publish-ready, sales brief
% of products
Unsupported claims
% of products
Failed outputs
% of products
1 GPT-6 LunaOpenAI
$0.0005
55.4%55.4%9.5%0.0%
2 Gemini 3.5 Flash LiteGoogle
$0.0020
16.1%3.6%35.7%0.0%
3 DeepSeek V4.1 FlashDeepSeek
$0.0061
44.6%21.4%11.3%0.0%
4 Claude Haiku 4.5Anthropic
$0.0061
1.8%0.0%80.4%0.0%
5 GLM 5V TurboZ.aiFailed outputs
$0.0070
0.0%0.0%57.1%32.1%
6 Mistral Medium 3.5Mistral
$0.0080
19.6%7.1%51.2%0.0%
7 GPT-6.1 SolOpenAI
$0.0084
73.2%67.9%0.6%0.0%
8 GPT-6 SolOpenAI
$0.0085
62.5%64.3%3.0%0.0%
9 Gemini 3.8 FlashGoogle
$0.0103
37.5%3.6%30.9%0.0%
10 Muse Spark 1.3Meta
$0.0164
46.4%19.6%13.1%0.0%
11 Claude Sonnet 5.5Anthropic
$0.0172
32.1%12.5%37.5%0.0%
12 Grok 4.7xAI
$0.0237
53.6%37.5%13.1%0.0%
13 Qwen3.8 Max (0902)AlibabaFailed outputs
$0.0256
33.9%1.8%22.6%3.6%
14 Gemini 3.1 Pro PreviewGoogle
$0.0355
41.1%10.7%26.8%0.0%
15 GPT-6 AstraOpenAI
$0.0371
75.0%67.9%1.2%0.0%
16 Claude Opus 5.5Anthropic
$0.0400
58.9%17.9%14.9%0.0%
17 Kimi K3Moonshot AI
$0.0469
41.1%1.8%15.5%0.0%
18 Claude Fable 5.1Anthropic
$0.0991
26.8%1.8%48.2%0.0%

Each model runs at its provider's default reasoning setting. Some providers think at length by default and others barely at all, so this is what you get without tuning.

Real outputs

The same product given to two models, from the published runs. A listing may use the supplier's copy, but not where the label says otherwise or the claim needs proof the seller does not have.

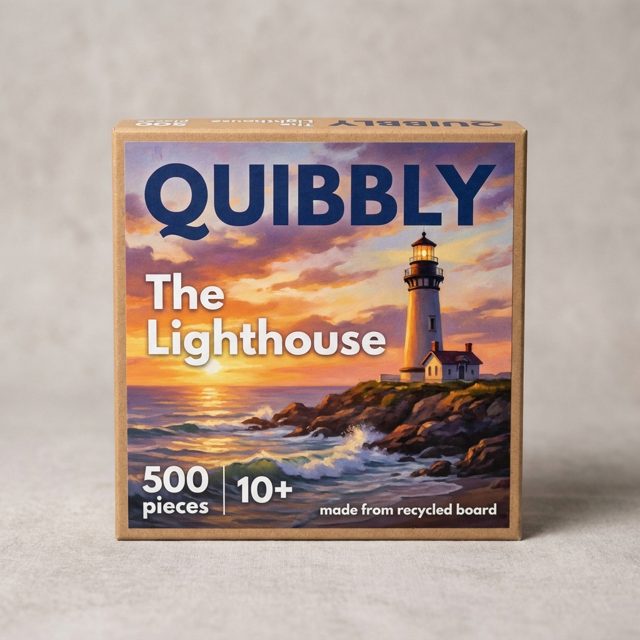
Quibbly Lighthouse Jigsaw Puzzle, as the model saw it

Quibbly Lighthouse Jigsaw Puzzle

Toys · Sales brief

Supplier copy “Quibbly The Lighthouse, a 1000-piece jigsaw made in the UK from recycled board, with a free poster.”

GPT-6 Astra✓ Publish-ready

Quibbly The Lighthouse Jigsaw Puzzle, 500 Pieces, Ages 10+

  • 500-piece jigsaw featuring a lighthouse above a rocky coastline.
  • Golden sunset, rolling waves and a glowing lantern bring the coastal scene to life.
  • Made from recycled board.
  • Suitable for ages 10 and over.

Piece together a dramatic coastal sunset with Quibbly The Lighthouse, a 500-piece jigsaw puzzle for ages 10 and over. The artwork features a tall lighthouse with a glowing lantern, a small keeper’s house and waves breaking against a rocky shore. Orange and purple clouds sweep across the sky, while golden sunlight reflects on the sea.

Gemini 3.5 Flash Lite✗ Not publish-ready

Quibbly The Lighthouse Jigsaw Puzzle 1000 Pieces

  • Engaging 1000-piece jigsaw puzzle featuring a scenic coastal lighthouse at sunset
  • Crafted from durable recycled board for a sustainable puzzling experience
  • Stunning artwork captures crashing waves, rocky shores, and a vibrant evening sky
  • Designed for puzzle enthusiasts and recommended for ages 10 and up

Immerse yourself in a tranquil coastal escape with the Quibbly The Lighthouse Jigsaw Puzzle. This captivating 1000-piece challenge invites you to piece together a breathtaking seaside scene complete with a majestic lighthouse standing tall against a glowing sunset, dramatic clouds, and gentle ocean waves crashing onto rocky shores.

Why it is not publish-ready
  • Quibbly The Lighthouse Jigsaw Puzzle 1000 PiecesContradicted by the pack. The lid is printed “500 pieces”.
and 8 more issues found by the judge
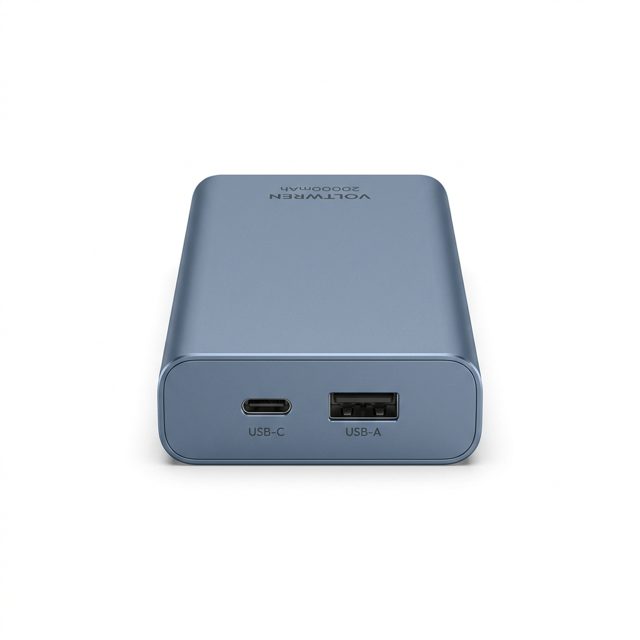
Voltwren 20,000 mAh Power Bank, as the model saw it

Voltwren 20,000 mAh Power Bank

Electronics · Factual brief

Supplier copy “Voltwren 20,000 mAh power bank with 65W fast charging for laptops, phones and tablets. Airline approved. USB-C and USB-A ports.”

GPT-6 Astra✓ Publish-ready

Voltwren 20,000 mAh Power Bank, Blue-Grey, USB-C and USB-A

  • 20,000 mAh capacity, with the capacity printed on the casing.
  • One USB-C port and one USB-A port.
  • Blue-grey casing with a smooth finish.
  • Rounded rectangular body with labelled ports on one end.

The Voltwren power bank has a 20,000 mAh capacity and a blue-grey casing with rounded corners and a smooth finish. One USB-C port and one USB-A port sit side by side on the end panel, with their connector types labelled underneath. The broad upper surface carries the Voltwren name and capacity marking.

Gemini 3.1 Pro Preview✗ Not publish-ready

Voltwren 20,000 mAh Power Bank, 65W, USB-C & USB-A, Blue

  • 20,000 mAh battery capacity
  • 65W fast charging supported
  • Equipped with one USB-C and one USB-A port
  • Suitable for charging laptops, phones, and tablets

Keep your devices powered on the go with the Voltwren 20,000 mAh Power Bank. Designed for versatility and convenience, it supports 65W fast charging and is suitable for a range of devices including laptops, mobile phones, and tablets. The power bank is equipped with both a USB-C and a USB-A port, allowing you to charge multiple devices efficiently.

Why it is not publish-ready
  • Airline approved for travelNeeds proof the seller does not have. An approval the seller would have to prove; nothing on the product shows it.
and 3 more issues found by the judge
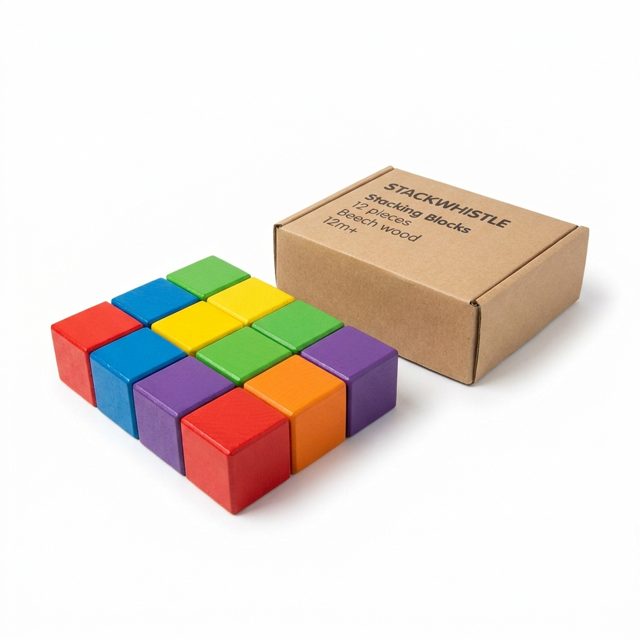
Stackwhistle Wooden Stacking Blocks, as the model saw it

Stackwhistle Wooden Stacking Blocks

Toys · Sales brief

Supplier copy “Stackwhistle Stacking Blocks: 12 solid beech blocks with non-toxic water-based paint, FSC certified wood, Montessori approved. 12m+.”

GPT-6 Astra✓ Publish-ready

Stackwhistle Wooden Stacking Blocks, 12 Pieces, Multicoloured, 12m+

  • 12 beech wood blocks for stacking, arranging and building.
  • Bright multicoloured designs include red, blue, green, yellow, orange and purple.
  • Cube-shaped blocks with flat faces for simple stacking play.
  • Suitable for children aged 12 months and over.

Build colourful towers and explore different arrangements with Stackwhistle Wooden Stacking Blocks. This 12-piece set is made from beech wood, with bright colours including red, blue, green, yellow, orange and purple. The cube-shaped blocks have flat faces for stacking, lining up and creating simple constructions, giving children a straightforward way to explore hands-on building play.

Claude Haiku 4.5✗ Not publish-ready

Stackwhistle Wooden Stacking Blocks, 12 Pieces, Multicoloured

  • Set of 12 solid beech wood blocks in vibrant colours for creative stacking and building play
  • FSC-certified sustainable wood with non-toxic water-based paint finish
  • Develops fine motor skills, hand-eye coordination and spatial awareness
  • Suitable from 12 months old; safe for babies and toddlers

Stackwhistle Wooden Stacking Blocks offer hours of creative play and learning for babies and toddlers from 12 months old. This set contains 12 solid beech wood blocks, each finished with vibrant, non-toxic water-based paint in red, blue, yellow, green, orange and purple.

Why it is not publish-ready
  • FSC-certified sustainable wood with non-toxic water-based paint finishNeeds proof the seller does not have. A certification and a safety claim on a child's toy; the box shows neither.
  • Montessori-approved learning toy for natural child developmentNeeds proof the seller does not have. An endorsement nothing on the box supports.
and 22 more issues found by the judge

More from the results

Publish-ready rate against cost

Cost to enrich 10,000 products at the run date's prices, on a log scale. Up and to the left is better.

0%20%40%60%80% $1$10$100$1,000 Cost per 10,000 products (log scale) Reliably publish-ready, % Muse Spark 1.3: 46.4%, $164.18 DeepSeek V4.1 Flash: 44.6%, $60.70 Gemini 3.1 Pro Preview: 41.1%, $354.64 Kimi K3: 41.1%, $468.95 Gemini 3.8 Flash: 37.5%, $102.92 Qwen3.8 Max (0902): 33.9%, $255.72 Claude Sonnet 5.5: 32.1%, $171.91 Claude Fable 5.1: 26.8%, $991.28 Mistral Medium 3.5: 19.6%, $80.05 Gemini 3.5 Flash Lite: 16.1%, $20.47 Claude Haiku 4.5: 1.8%, $61.38 GLM 5V Turbo: 0.0%, $70.11 GPT-6 Astra: 75.0%, $371.20 GPT-6.1 Sol: 73.2%, $83.84 GPT-6 Sol: 62.5%, $85.18 Claude Opus 5.5: 58.9%, $400.06 GPT-6 Luna: 55.4%, $4.77 Grok 4.7: 53.6%, $237.19 GPT-6 Astra GPT-6.1 Sol GPT-6 Sol Claude Opus 5.5 GPT-6 Luna Grok 4.7

Why listings fail: factual brief

Share of products failing each check, averaged over three runs. A listing can fail several at once; any one stops it going live.

ModelNo usable outputUnsupported claimsWrong attributesNot findableWrong categoryChannel rulesUK information
GPT-6 AstraOpenAI0.0%1.2%17.3%6.0%1.8%0.0%0.0%
GPT-6.1 SolOpenAI0.0%0.6%16.7%4.8%1.8%0.0%0.0%
GPT-6 SolOpenAI0.0%3.0%14.3%7.7%3.6%0.0%0.0%
Claude Opus 5.5Anthropic0.0%14.9%15.5%3.0%1.8%0.0%0.0%
GPT-6 LunaOpenAI0.0%9.5%18.4%10.1%1.8%0.0%0.0%
Grok 4.7xAI0.0%13.1%15.5%5.4%2.4%0.0%0.0%
Muse Spark 1.3Meta0.0%13.1%16.7%6.0%4.2%0.0%0.0%
DeepSeek V4.1 FlashDeepSeek0.0%11.3%20.2%3.6%3.0%3.0%0.0%
Gemini 3.1 Pro PreviewGoogle0.0%26.8%14.9%7.7%1.8%1.2%0.0%
Kimi K3Moonshot AI0.0%15.5%24.4%4.2%3.0%0.6%0.0%
Gemini 3.8 FlashGoogle0.0%30.9%15.5%8.3%3.6%0.6%0.0%
Qwen3.8 Max (0902)Alibaba3.6%22.6%21.4%3.6%1.8%0.6%0.0%
Claude Sonnet 5.5Anthropic0.0%37.5%19.1%1.2%3.0%1.2%0.0%
Claude Fable 5.1Anthropic0.0%48.2%11.9%1.8%2.4%0.0%0.0%
Mistral Medium 3.5Mistral0.0%51.2%30.9%14.3%11.3%0.0%0.0%
Gemini 3.5 Flash LiteGoogle0.0%35.7%34.5%20.2%9.5%1.8%0.0%
Claude Haiku 4.5Anthropic0.0%80.4%48.2%8.9%7.7%7.7%0.0%
GLM 5V TurboZ.ai32.1%57.1%13.1%5.4%1.2%1.2%0.0%

Why listings fail: sales brief

The same checks when the model is asked for copy that sells.

ModelNo usable outputUnsupported claimsWrong attributesNot findableWrong categoryChannel rulesUK information
GPT-6 AstraOpenAI0.0%3.0%20.2%5.4%1.8%0.0%0.0%
GPT-6.1 SolOpenAI0.0%3.6%19.1%5.4%1.8%0.0%0.0%
GPT-6 SolOpenAI0.0%4.8%13.7%7.1%3.0%0.6%0.0%
Claude Opus 5.5Anthropic0.0%57.1%15.5%1.8%1.8%0.6%0.0%
GPT-6 LunaOpenAI0.0%7.7%19.1%10.1%0.0%0.0%0.0%
Grok 4.7xAI0.0%26.2%15.5%4.2%2.4%0.0%0.0%
Muse Spark 1.3Meta0.0%51.2%14.3%5.4%3.6%0.0%0.0%
DeepSeek V4.1 FlashDeepSeek0.6%39.3%20.2%3.6%2.4%1.8%0.0%
Gemini 3.1 Pro PreviewGoogle0.0%70.8%16.1%6.0%1.8%4.8%0.0%
Kimi K3Moonshot AI0.6%81.0%20.8%3.0%4.2%0.6%0.0%
Gemini 3.8 FlashGoogle0.0%82.7%11.9%8.9%3.0%0.6%0.0%
Qwen3.8 Max (0902)Alibaba3.6%83.3%19.6%1.8%2.4%3.0%0.0%
Claude Sonnet 5.5Anthropic0.0%60.7%20.8%0.6%3.0%1.2%0.0%
Claude Fable 5.1Anthropic0.0%86.9%14.9%1.8%1.8%0.6%0.0%
Mistral Medium 3.5Mistral0.0%83.9%36.3%10.1%13.1%3.0%0.0%
Gemini 3.5 Flash LiteGoogle0.0%81.0%35.1%21.4%10.7%1.8%0.0%
Claude Haiku 4.5Anthropic0.0%95.8%51.2%6.5%6.5%22.6%0.0%
GLM 5V TurboZ.ai82.1%17.9%3.6%1.8%1.2%0.6%0.0%

How CatalogBench works

  1. 1

    The feed row

    A sparse supplier row: title, price, a few attributes, and the supplier's marketing text, usable unless the pack says otherwise.

  2. 2

    The photos

    One to three product photos, including labels with the real facts: volume, strength, origin, ingredients.

  3. 3

    The listing

    The model fills missing attributes and writes the title, highlights, description, alt text, search keywords and category.

  4. 4

    The checks

    Rules check attributes and channel limits, a judge answers yes/no questions against the evidence, and a search test checks shoppers can find it.

  5. 5

    Publish-ready?

    Only if every blocking check passes. Three runs; the headline counts products that passed in all three.

The task

Retailers increasingly let AI write their product listings from a supplier feed and a few photos. The risky part is not the prose: it is attributes that are guessed, claims the pack contradicts or the law requires proof for, and listings that no shopper will find.

Each of the 56 public products is invented, with generated photos that carry real-looking labels. Every feed row hides traps: missing attributes only the photos can answer, a supplier claim the label contradicts, and tempting claims such as “award-winning” with no evidence at all.

Two briefs

Factual
Write an accurate listing from the evidence.
Sales
Write copy that sells. The same facts, the same checks: persuasive is fine, unsupported is not.

What stops a listing going live

Unsupported claims
A specific, checkable claim with no support. Supplier copy counts as support unless the label or photo contradicts it, or it is a claim UK rules require the seller to prove (health, organic, environmental, safety and certification claims, free-from claims, endorsements, awards). Puffery such as “durable” or “soft feel” is not a claim.
Wrong attributes
A wrong, missing or invented value, or a feed/photo conflict that was not flagged.
UK information
Statements UK rules require, such as age warnings.
Channel rules
Lengths, formats and banned terms.
Category
The wrong category, or the wrong variant in the title.
Findability
Two shopper searches per product against near-identical rival listings; the listing must win on what the shopper asked for.

Reading the results

Content quality (coverage, visual detail, key facts in the title) is scored separately and does not stop a listing going live. Costs are the prices charged on the run date and are shown per 10,000 products, a typical catalogue refresh.

What it measures

  • Attributes read from the images, not guessed
  • Supplier claims checked against the pack and UK rules
  • Required UK product information included
  • Listings that shoppers can find in search

What it does not measure

  • Conversion or sales impact
  • Real product photography (a real-photo slice is planned)
  • Writing style beyond the listed checks

Method

  • Rule-based checks first; judged checks are yes or no
  • The judge was checked for bias against Gemini and Claude judges
  • Private products are held back so the set can be refreshed

Checking the judge

The judge is an OpenAI model, and OpenAI models lead this table, so we checked it for bias under the current rules. Gemini 3.1 Pro and Claude Opus 5.5 judged the same outputs from five models on a calibration set. All three judges gave the OpenAI models the same or nearly the same results, and put the models in the same order on the sales brief; on the factual brief only Gemini differed, ranking Claude Opus 5.5 above GPT-6 Luna. The Claude judge was stricter on Claude Opus 5.5 than the OpenAI judge was. The judges differ mainly in how many claims they flag: Gemini flags the fewest.

Failures

Failures count against a model: a product with no usable output is a failed listing. They are listed here so you can see why.

  • GLM 5V Turbo: invalid JSON (raw line breaks inside text): 50 of 168 attempts; invalid JSON: 4 of 168 attempts.
  • Qwen3.8 Max (0902): reply cut off at the token limit: 6 of 168 attempts.
Run this on your catalogue. The same checks, on a sample of your own products.Catalogue feed diagnostic →