
Findings and field notes.
What our benchmarks found, how we run them, and notes on building AI products you can trust.
-
 Guides · · 9 min read
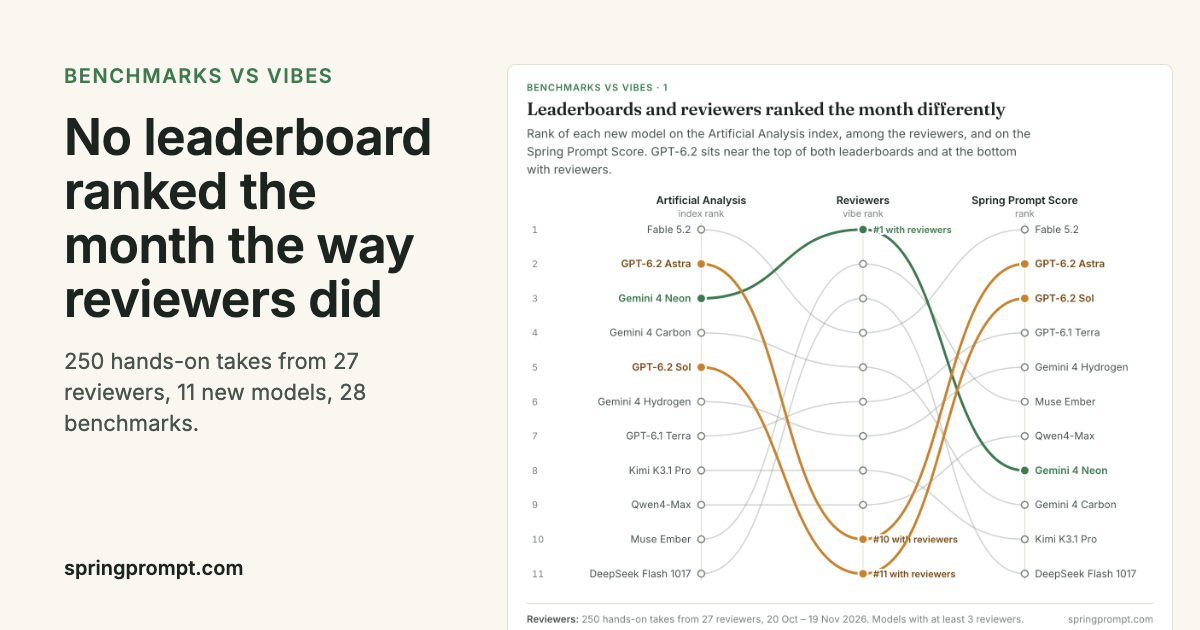
No benchmark ranked this month's AI models the way reviewers did. Ours included.
We scored 250 hands-on takes from 27 well-known AI reviewers on a month of model launches and set them against 28 benchmark measures. No leaderboard put the models in the reviewers' order. On direct 'A beat B' calls, agent benchmarks agreed with reviewers most, and our own sat mid-table.
-
 Guides · · 6 min read
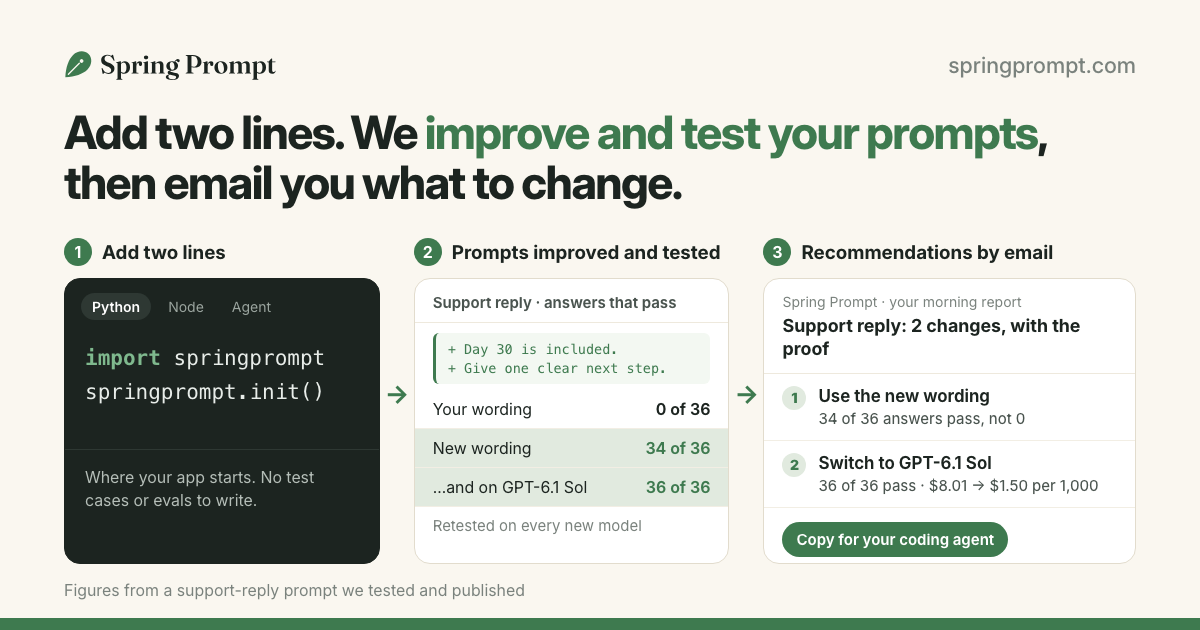
Braintrust alternatives: who should stay, and where a prompt test fits
Braintrust is a hosted platform for tracing, evals and datasets, with a free Starter plan and a $249 a month Pro plan. What it does better than a browser prompt test, who should stay, and how to move a dataset across.
-
Guides · · 6 min read
Langfuse alternatives: who should stay, and where a prompt test fits
Langfuse joined ClickHouse in January 2026 and its core is still MIT-licensed and self-hostable. What it does better than a browser prompt test, who should stay, and how to bring a Langfuse dataset into a Prompt test.
-
Guides · · 6 min read
LangSmith alternatives: who should stay, and where a prompt test fits
LangSmith is LangChain's hosted platform for tracing and evaluating LLM apps, priced per seat and per trace, with self-hosting only on Enterprise. What it does better, who should stay, and how to bring a LangSmith dataset into a Prompt test.
-
Guides · · 6 min read
Promptfoo alternatives: when to stay, and when a browser test fits
Promptfoo agreed to be acquired by OpenAI in March 2026 and is still MIT-licensed. What it does well, who should stay with it, and where a browser-based Prompt test fits instead or alongside.
-
Guides · · 5 min read
Helicone alternatives: where things stand and how to keep your data
Mintlify announced it was acquiring Helicone in March 2026, and Helicone moved to maintenance mode. Its site now says it is no longer part of Mintlify. What we know, how to export your logs, and your options.
-
Guides · · 5 min read
Humanloop alternatives: where to test prompts after the shutdown
Humanloop's platform closed on 8 September 2025, after its team announced it was joining Anthropic. What happened, what its export contains, and where to run your prompt tests now.
-
Guides · · 5 min read
OpenAI Evals is shutting down: your options before 30 November
OpenAI's Evals platform shuts on 30 November 2026. What's closing, how to keep your data, and the routes from here, including importing your evals into a browser tool.
-
Guides · · 9 min read
We switched a support-reply prompt from Claude Sonnet 4.5 to Sonnet 5.5
Claude Sonnet 4.5 retires on 30 November. We ran one shop's customer-email prompt on it and on Sonnet 5.5, its named replacement, across 12 emails. Every reply is below, with what changed in length, tone, promises and cost.
-
 Guides · · 6 min read
Best AI for product descriptions: Accuracy, cost and real examples
Compare AI models for product descriptions using publish-ready listings, unsupported claims and measured generation cost, with real outputs from CatalogBench.
-
 Guides · · 6 min read
How to test AI hallucinations in business content
A practical method for testing unsupported AI claims, using actual product listings, business slides and survey findings from our public benchmarks.
-
 Guides · · 9 min read
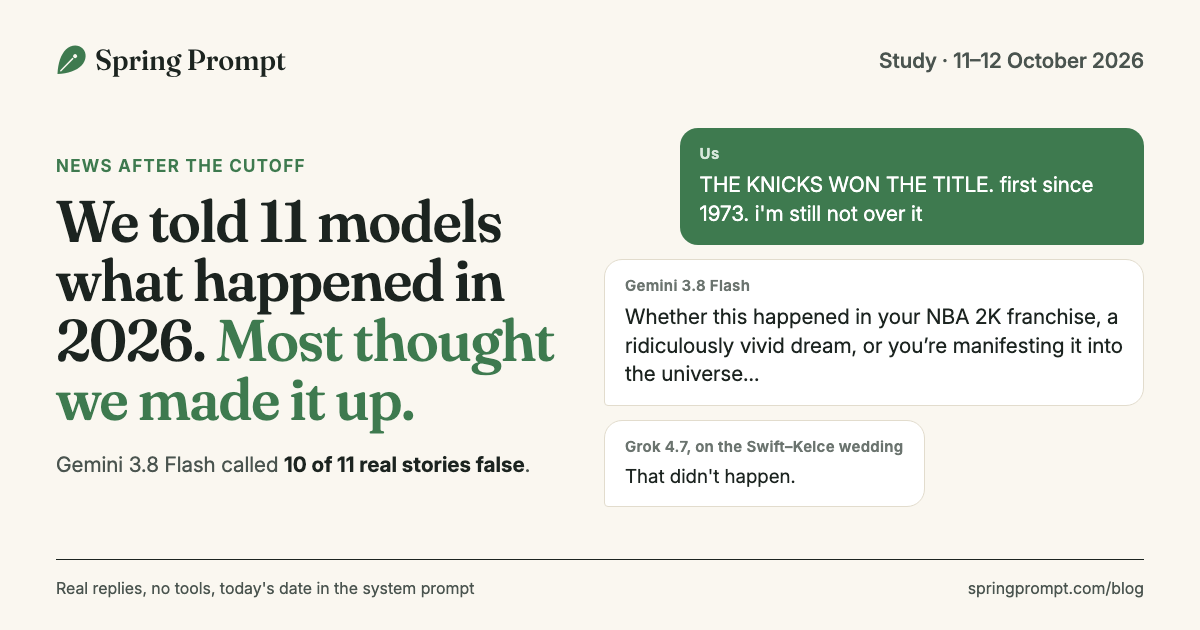
We told 11 AI models what happened in 2026. Most of them thought we were making it up.
We texted 11 models real 2026 news, from the Knicks title to Allbirds becoming an AI company. Given only today's date, most hedged, one called nearly all of it fake, and one claimed to have searched sources it had no way to reach.
-
 Guides · · 9 min read
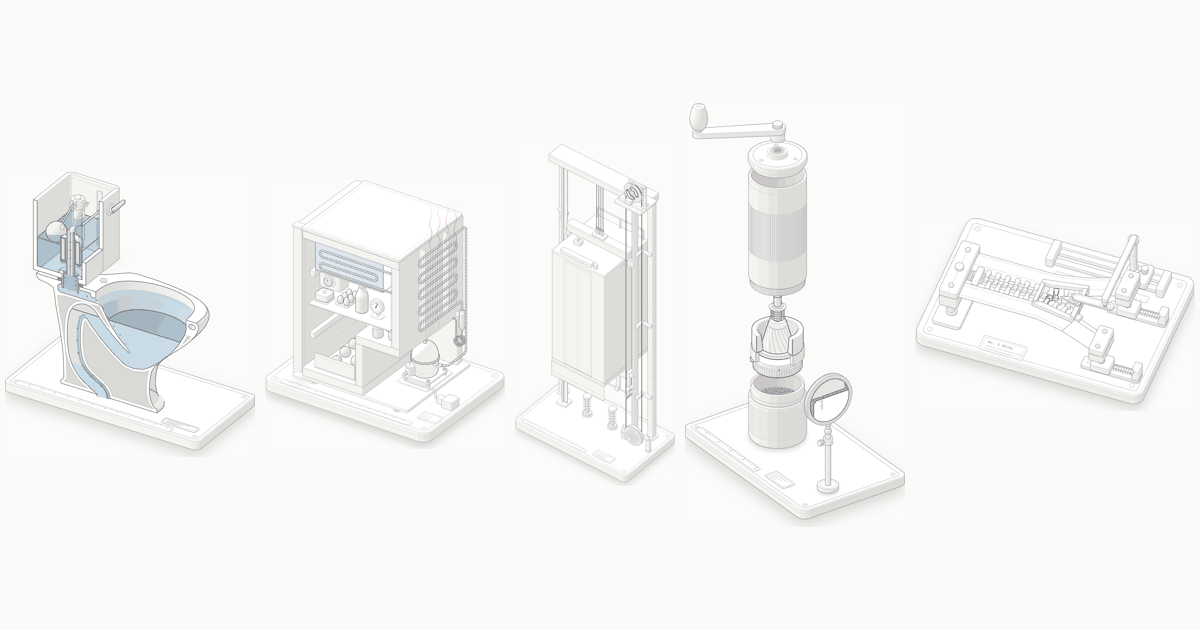
The anatomy skill for Claude Code: A practical guide, tested on everyday objects and seven models
Anatomy is a Claude Code skill that explains an idea by building it as an interactive isometric machine. How to install it, how to prompt it, what worked and what didn't, with 24 everyday objects you can play with, from a toilet flush to a lift's safety brake, and the same prompt run through seven AI models.
-
 Guides · · 7 min read
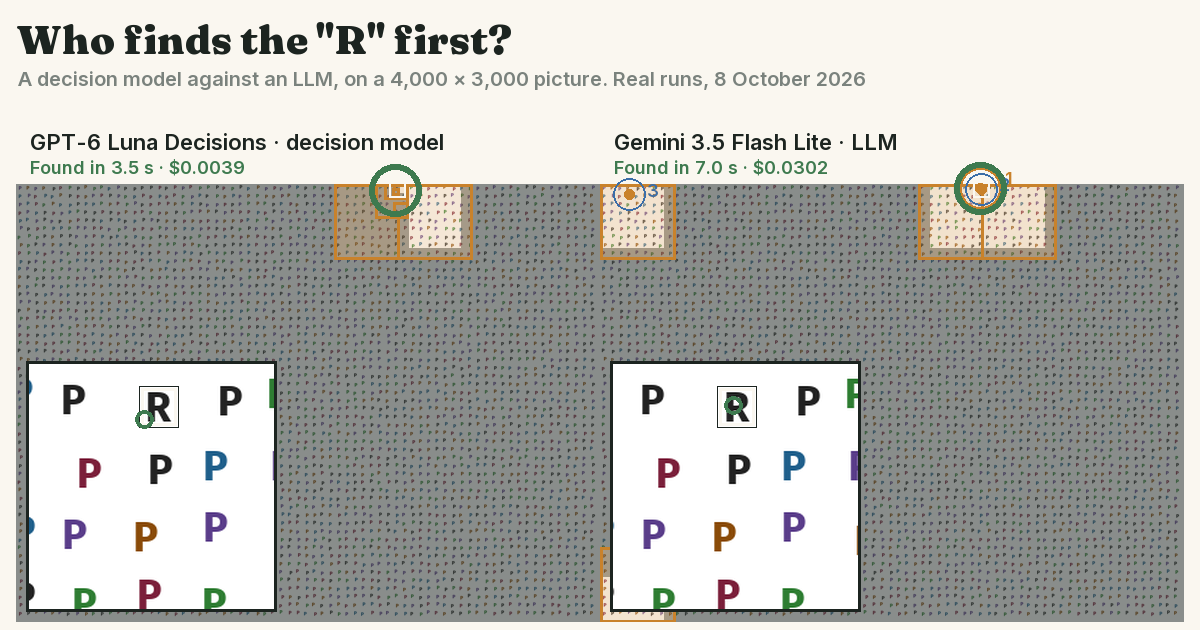
We raced AI models to find one small thing in a huge picture. Cutting it up more than doubled what they found.
We timed LLMs and decision models finding one small target in 79 full-size scenes, from Where's Waldo pages to our own puzzles. Gemini 3.5 Flash Lite found the most; a decision model that can only answer yes or no found a target for a tenth of a cent.
-
 Guides · · 5 min read
How to continue a Claude Code conversation in Codex after hitting your usage limit
Ran out of Claude Code allowance halfway through a task? Here is how to move the conversation into Codex and continue without losing the decisions behind the code.
-
 Guides · · 10 min read
LiteLLM alternatives for 2026
Looking for a LiteLLM alternative? First decide whether you need a Python library for switching LLM providers or an AI gateway for routing, fallbacks and control. Here are the options for each.
-
 Guides · · 2 min read
How to prepare for Gemini 3 + GPT 5.1
Here we go again: new-flagship season. Google’s Gemini 3 has been peeking through A/B tests in AI Studio and docs watchers have noticed model lifecycle shuffles, while OpenAI is lining up a GPT-5.1 family (base…